Context and KV Cache: How an LLM Reuses Earlier Tokens
AI Foundations #17 follows KV state through prefill, decoding, prefix reuse, edited prompts, and request completion, explaining when cached work remains valid.
Approximately 6 min read · AI Foundations / Lesson 17
An autoregressive language model predicts one token, appends it, and predicts again. Recomputing every earlier attention key and value at every step would waste most of the work already completed. The KV cache stores that reusable state.
Context and KV cache describe different parts of the same request. The context is the token history available for the current prediction. The KV cache is a runtime representation of attention state calculated from that history.
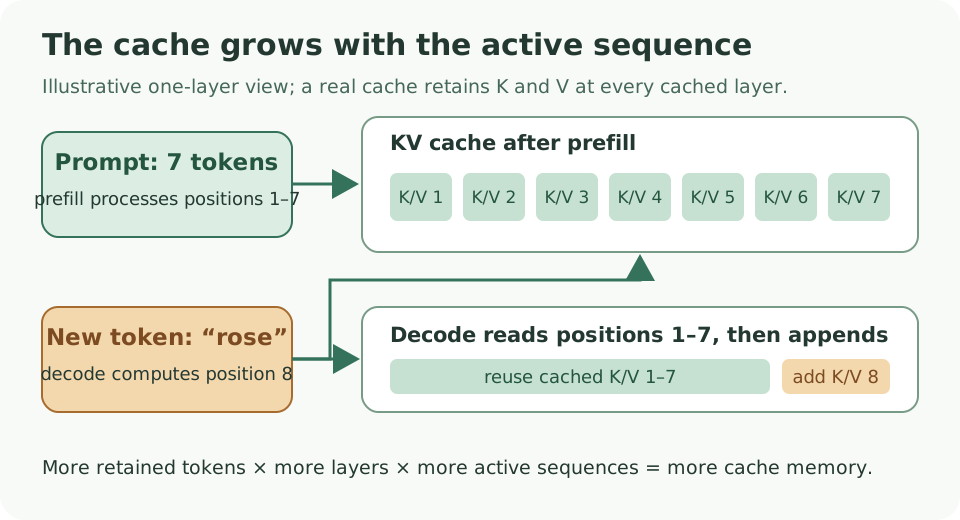
Prefill creates cache entries for the prompt. Each decode step reads the existing cache and appends one new position per active layer.
Follow one request
Consider the prompt The bond price fell because rates. After tokenization, assume it occupies seven token positions. During prefill, the model processes those positions through its Transformer layers.
At an attention layer, each position produces a query, key, and value. Causal attention prevents a position from using information from future positions. For later decoding, the important reusable results are the earlier keys and values.
If the model selects rose as the next token, the sequence now has eight positions. The runtime calculates the new token’s state, compares its query with cached keys, combines the corresponding values, and stores the new key and value. The next step repeats with nine positions.
The cache grows with the active sequence because every retained position needs attention state at every cached layer.
The context window is a capacity limit
The context window limits how many token positions the model and runtime can use for one active sequence. Input and generated output share that capacity.
An 8,192-token limit with 6,000 tokens of system instructions, tool definitions, retrieved text, and chat history leaves at most 2,192 positions for continuation. An application may reserve output space, reject an oversized request, or truncate selected input before inference begins.
The advertised model limit is only one boundary. The runtime may be configured for a smaller maximum, and available cache memory may impose a practical limit below either number. What Does Context Length Mean? covers those three limits in detail.
Why keys and values are reusable
In causal self-attention, an earlier token cannot depend on a token generated later. Once the earlier positions have been processed for the current sequence, their cached keys and values do not need to change when one new token is appended.
The new token still needs fresh computation through the model. Its query attends over the retained keys, including the new position where permitted, and the resulting representation continues through later sublayers. The cache removes repeated projections for earlier positions; it does not make decoding free.
Queries are usually temporary for a decode step. Keys and values are retained because future queries need them. That is the origin of the name KV cache.
Reuse follows the shared token prefix
A cache belongs to a particular token sequence and model computation. Appending a token preserves the earlier causal history, so those earlier keys and values remain useful. Editing an earlier position changes the history seen by later positions.
Consider a conversation with 1,000 cached tokens:
| Next action | Which work can be reused? |
|---|---|
| Append another user message after the existing history | The unchanged 1,000-token prefix, if the runtime retains it |
| Change token 600 | The unchanged prefix before the edit; the changed suffix needs processing again |
| Change the system instruction at the start | Later state was computed under a different history and needs recomputation |
| Load different model weights | The previous model’s cache is not a replacement for a new forward pass |
A visible sentence is not enough to identify a shared prefix. Role markers, tool definitions, whitespace, and the chat template affect the actual token sequence. An application that rebuilds a prompt differently can lose reuse even when the conversation looks unchanged on screen.
A request has a cache lifecycle
During prefill, the runtime creates state for the prompt. During decode, it appends state for each processed continuation token. When the request ends, the runtime may free that storage, retain the sequence for a later turn, or keep eligible blocks in a prefix-cache pool.
Those are runtime choices. Saving a conversation’s text to disk does not automatically save a usable KV cache, and a new HTTP request does not automatically inherit the state of an earlier request.
When testing reuse, compare the exact formatted prefix and inspect the runtime’s cache-hit or prompt-processing measurements. Keep cold-prefill and reused-prefix timings separate. Otherwise a fast second request can be mistaken for an improvement in the model’s raw prompt-processing speed.
Cache sizing is covered in What Is a KV Cache?, including a layer/head/precision calculation. This lesson follows how that state is created, reused, invalidated, and released.
Prefill and decode stress hardware differently
Prefill processes many prompt positions and often exposes substantial parallel work. Decode handles one new position per active sequence at a time and repeatedly reads model weights plus growing cache state.
This is why deployments report prompt-processing throughput and generation throughput separately. A configuration can prefill quickly but decode slowly, or begin quickly at short context and slow as the retained cache grows.
Continuous-batching servers also manage caches for many requests. They need to allocate and reclaim blocks as sequences enter, grow, finish, or get preempted. PagedAttention applies virtual-memory ideas to this allocation problem so cache storage does not require one perfectly contiguous reservation for each sequence.
What the cache does not do
The KV cache is not permanent memory and it does not update model weights. Removing a request’s cache removes that request’s reusable attention state. Starting a fresh conversation normally creates a fresh sequence unless an application deliberately reuses a compatible prefix cache.
It is also unsafe to assume a cache can move between arbitrary model artifacts or runtime configurations. The state depends on the model layers, token sequence, positional treatment, cache format, and often implementation details.
Diagnose context and memory problems separately
When a long request fails, first identify the boundary:
- count the actual formatted input tokens;
- compare input plus requested output with the runtime limit;
- inspect the cache allocation and precision;
- include concurrency in the memory estimate;
- check whether another buffer, rather than the KV cache, produced the allocation error.
Reducing the model’s weight precision may free memory for cache, but it does not directly shrink an FP16 KV cache. Reducing sequence length, concurrency, KV precision, or cached layer/head state targets the cache itself. What Is a KV Cache? provides a shorter introduction, while this lesson supplies the request lifecycle and sizing calculation.