Mixture of Experts: How MoE Models Activate Only Part of the Network
AI Foundations #19 follows tokens through an MoE router and explains expert selection, active versus total parameters, load balance, memory, and inference cost.
Approximately 4 min read · AI Foundations / Lesson 19
A dense Transformer applies the same feed-forward network to every token at a layer. A sparse Mixture-of-Experts model replaces some of those feed-forward blocks with several expert networks and a router. For each token, the router selects a small subset of experts.
This creates the central MoE tradeoff: the checkpoint can contain many parameters while one token activates only part of them. The model may gain capacity without multiplying arithmetic by the full expert count, but the weights still need storage and the routing must be executed efficiently.
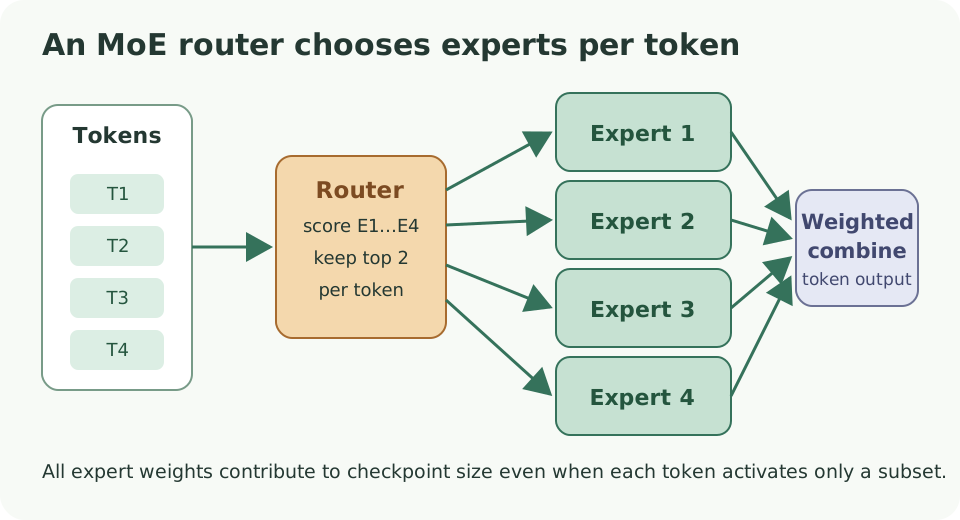
This illustrative top-2 layer sends each token to two experts. Routing decisions are made per token, so different tokens can use different expert pairs.
What an expert is
In many Transformer MoE designs, an expert is a feed-forward subnetwork. Attention remains shared, while selected feed-forward layers contain several alternative parameter sets.
Calling them experts does not mean one network has a human-readable job such as finance or translation. Specialization can emerge from training, but a router normally works with numerical scores rather than named skills.
The exact architecture varies. Mixtral uses sparse expert feed-forward blocks with top-2 routing. Switch Transformer emphasized top-1 routing. DeepSeekMoE introduced finer-grained experts and shared experts. Any explanation of active parameters must therefore name the model rather than assume one universal layout.
Follow one token through a top-2 layer
Assume a layer has four routed experts. The router reads a token representation and produces four scores:
| Expert | Router score |
|---|---|
| E1 | 0.55 |
| E2 | 0.25 |
| E3 | 0.15 |
| E4 | 0.05 |
With top-2 routing, E1 and E2 receive the token. Each expert transforms the representation using its own weights. The layer combines their outputs using routing weights derived from the selected scores.
The next token can take another route. A code token, punctuation mark, and ordinary word in the same sequence are not required to visit the same experts.
Routing is repeated at every MoE layer. Saying that a request “uses two experts” is therefore incomplete: it can use two experts per token per routed layer, and the chosen pair can change at each location.
Total and active parameters answer different questions
Total parameters describe everything stored in the checkpoint. They influence artifact size and the memory needed to keep all weights available.
Active parameters describe the subset involved in one token’s forward path under a particular routing scheme. They help explain arithmetic cost, but the advertised number may include shared attention, embeddings, normalization, shared experts, and other dense components in addition to selected routed experts.
A model with 100 billion total parameters and 20 billion active parameters is not equivalent to a dense 20-billion-parameter model. Architecture, training data, expert organization, memory access, and routing overhead all differ.
Sparse computation does not make the checkpoint small
All expert weights must be stored somewhere the runtime can access. On one GPU, a large MoE may fail to fit even though few experts activate for each token. Quantization can reduce the weight footprint, and expert offloading can place some weights in host memory, but both introduce format and data-movement considerations.
If selected expert weights have to cross a slow link for each layer or batch, transfer latency can erase the arithmetic advantage. Keeping frequently used weights resident, batching tokens by expert, and using optimized grouped matrix multiplication are important runtime problems.
The workload matters. With a larger batch, many tokens can be grouped for each expert. With batch one, routes may offer less work per expert call and expose more launch or transfer overhead.
Training must prevent routing collapse
A router could learn to send most tokens to the same few experts. Those experts would become overloaded while others receive little training.
MoE systems use capacity rules, auxiliary objectives, routing noise, or other balancing methods to distribute work. If an expert exceeds its capacity during training, implementations may drop, reroute, or otherwise handle excess assignments. These choices affect optimization and are part of the model design, rather than an inference setting added later.
Shared experts provide another path. They process all tokens while routed experts handle more specialized transformations. This changes both the active-parameter calculation and the interpretation of routing balance.
What to check before running an MoE model locally
Read four pieces of the model configuration:
- number of routed experts;
- experts selected per token;
- dense, shared, and routed layer structure;
- total and reported active parameter counts.
Then inspect the artifact size, quantization, runtime support, and placement plan. A runtime may recognize the architecture but still lack an efficient kernel or offload path for its exact expert layout.
Measure load time, resident system memory, VRAM, prompt throughput, and decode throughput. Record context and batch size because they change both cache use and how much expert work can be grouped.
MoE makes a model conditionally sparse in computation. It does not make storage, routing, or memory placement disappear. That is the useful meaning behind “many total parameters, fewer active parameters.”