What Does Context Length Mean in an LLM?
Learn what LLM context length means, what counts toward the context window, how tokens, chat history, KV cache, VRAM, truncation, and long-context models work.
Approximately 4 min read
An LLM’s context window is the tokenized information available within an active sequence. It includes the prompt history and, within the supported sequence budget, generated continuation. A long advertised window tells you about capacity; useful performance also depends on how the model and application handle that capacity.
For deployment, keep three limits separate: what the model supports, what the runtime allocates and what the application actually sends.
Count tokens across the whole request
Tokens are vocabulary units produced by a tokenizer. A word may occupy one token or several, while code, numbers and different writing systems have their own patterns. Use the model’s tokenizer for a real budget instead of a fixed words-to-tokens conversion.
| Request component | Can consume context? |
|---|---|
| System instructions and chat-template markers | Yes |
| User messages and retained assistant messages | Yes |
| Tool definitions, calls and results | Yes |
| Retrieved documents or supplied code | Yes |
| New generated tokens | Must fit the applicable sequence budget |
Suppose a runtime allows an 8,192-token sequence. A 6,000-token input leaves at most 2,192 tokens for continuation before accounting for any additional template or request details. Setting a large output limit does not create more context.
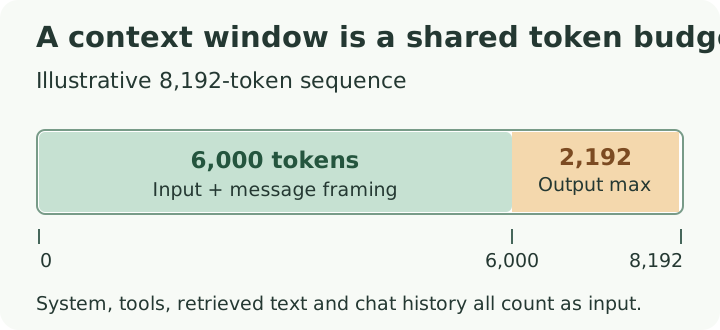
The split is an example, not a recommended allocation. Chat-template markers and other included content also consume tokens.
The three limits
Model capability comes from training, architecture and documented positional behaviour. Runtime configuration determines the usable context and associated allocations. Application policy determines which messages, documents and tools are included, truncated or summarized.
If a chat application forgets an early message, inspect that last layer. It may have dropped history or replaced it with a summary before calling the model. A model with a larger window cannot recover text the application did not send.
When a request reaches the limit, systems may reject it, truncate input, reduce output or manage older state. Inspect the actual request and runtime behaviour rather than relying on a generic “memory” setting in an interface.
Why longer context costs memory and time
Conventional transformer inference retains attention keys and values for processed positions. More cached tokens require more storage when the architecture and cache representation remain fixed. The number of layers, KV heads, head dimension, cache datatype and active sequences all influence the allocation.
GQA can reduce the KV-head count. Sliding-window layers can limit retained state. Hybrid models may add recurrent allocations with different scaling. Read the runtime’s cache and buffer logs for the actual model.
Prefill processes the prompt, while decode extends it. Increasing input length can therefore increase the wait before the first token and change later generation cost. A benchmark with a short prompt cannot predict the full experience of a long repository or document request.
The KV-cache guide works through a 4 GiB example and its scaling with context.
Position and long-context quality
Position encodings let a transformer distinguish where tokens occur. RoPE and its extensions influence how models behave at longer positions. Position Interpolation, YaRN and other scaling methods have specific assumptions and configurations.
Increasing a runtime’s context flag does not train the model to use that longer sequence well. Begin with the checkpoint’s documented configuration. Apply extension methods only with compatible model and runtime support, then evaluate the work you need to perform.
A needle-retrieval task checks one kind of access to long input. It does not settle whether the model can reconcile conflicting documents, follow dependencies in code or reason across many distant facts. Test those tasks directly if they motivate the larger window.
Choose a context for the task
For ordinary chat, a moderate window may be sufficient. For document work, budget the supplied text, instructions and output. For coding agents, include tool results and repository excerpts rather than counting only visible conversation messages.
Compare these approaches on the same task:
| Approach | Benefit | What to check |
|---|---|---|
| Longer context | More material supplied together | Memory, latency and whether relevant details are used |
| Retrieval | Selects a smaller relevant subset | Whether the needed evidence is retrieved |
| Summarization | Reduces retained text | Whether essential details survive compression |
Choose the smallest configuration that reliably preserves the information your task needs. Increase it deliberately, and repeat the same quality and latency checks after the change.