Quantization: How Fewer Bits Make Large Models Smaller
AI Foundations #18 explains post-training weight quantization, scale and rounding error, memory estimates, mixed precision, kernels, and quality tradeoffs.
Approximately 4 min read · AI Foundations / Lesson 18
Quantization stores or computes model numbers with lower precision. For local inference, the immediate benefit is memory: a model that cannot fit as FP16 weights may fit when its large weight tensors use a 4-bit representation.
The tradeoff is approximation. A quantized tensor reconstructs values close to the original weights rather than preserving every original bit. The practical question is whether that approximation retains the behavior needed for the target workload and runtime.
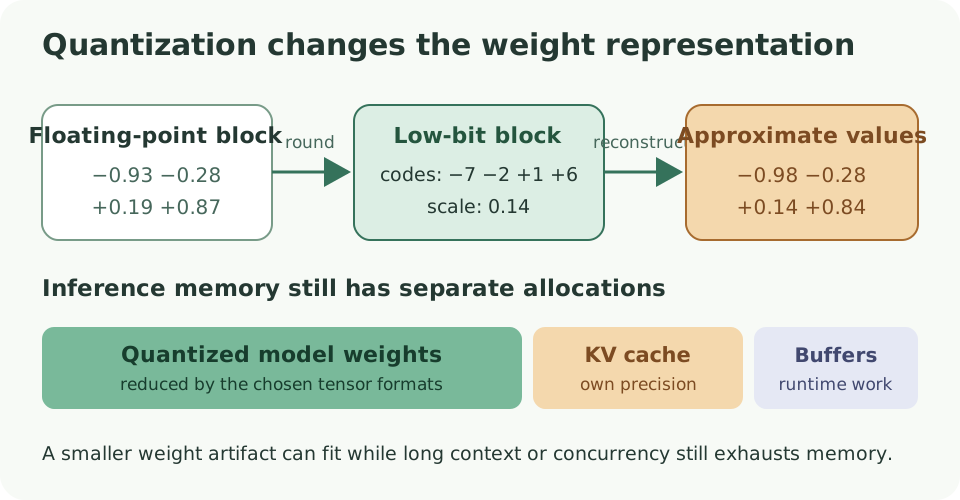
Weight quantization reduces the largest fixed allocation in many deployments. KV cache and working buffers have their own formats and must be budgeted separately.
From floating-point weights to low-bit codes
Post-training quantization starts with an already trained model. A converter groups weight values, records scaling information for each group or block, and maps the weights to a limited set of integer or low-bit codes.
A simplified symmetric mapping uses a scale s:
q = round(w / s) and reconstructed weight = s × q
w is the original weight, q is the stored code, and ŵ is the value reconstructed for computation. The difference w - ŵ is quantization error.
Real formats may use block-specific scales, offsets, codebooks, special packing, and different treatment for selected tensors. A label such as 4-bit therefore describes a family of representations rather than one universal encoding.
The idealized memory calculation
For weights alone, an initial estimate is
weight bytes ≈ parameters × bits per weight / 8
For a 7-billion-parameter model, that gives these payload estimates before metadata and mixed-precision tensors:
| Representation | Idealized weight payload |
|---|---|
| FP16 or BF16 | 14.0 GB |
| 8-bit | 7.0 GB |
| 4-bit | 3.5 GB |
Actual files are larger than a perfect parameters × bits calculation because formats store scales, tensor metadata, alignment, and sometimes higher-precision tensors. Gigabytes and gibibytes also differ, so compare the actual artifact size when planning a download or deployment.
Why a lower bit count can change quality
Two original weights can map to the same quantized code. Small errors accumulate as tensors participate in many matrix operations. Some layers and outlier values are more sensitive than others.
This is why good quantization methods do more than round every value with one global scale. They choose blocks, calibration statistics, clipping rules, or mixed-precision exceptions that reduce harmful error under a memory target. GPTQ and AWQ are examples of methods that use model behavior or activation information when choosing a quantized representation.
Quality also depends on the task. A format that preserves ordinary conversation may still change exact arithmetic, code generation, rare-language behavior, tool-call formatting, or long-context results. Compare artifacts on the workload that matters rather than relying on the quantization label alone.
Weight precision is only one memory control
An inference process can allocate:
- model weights;
- KV cache for active sequences;
- temporary compute and graph buffers;
- embeddings or multimodal components;
- runtime and driver memory.
Quantizing the weights directly reduces the first item. It does not automatically change KV-cache precision. A model can fit after weight quantization and still run out of memory when context length or concurrency causes the cache to grow.
This boundary is useful when diagnosing an out-of-memory error. If loading fails, reduce the artifact size or device placement. If a long request fails after loading, inspect context, cache, batch size, and working buffers.
Smaller files are not automatically faster
Lower precision can reduce memory traffic and allow more of a model to remain on a fast device. That often improves local inference. It can also be slower when the runtime lacks an optimized kernel, must repeatedly unpack or convert values, or splits work inefficiently across CPU and GPU.
Performance therefore depends on the combination of model architecture, quantization format, runtime build, kernel support, hardware, context, and batch settings. Compare prompt processing and token generation separately, because a format can affect them differently.
Reading GGUF quantization labels
GGUF is a container used by the GGML and llama.cpp ecosystem. Names such as Q4_K_M, Q5_K_M, or Q8_0 identify tensor quantization recipes used in an artifact. They do not guarantee a fixed quality score or runtime speed across all models.
Use the label to narrow candidates, then verify:
- the source model and revision;
- the converter and quantization method;
- the actual file size and tensor inventory;
- runtime support for that type;
- quality and speed on a controlled local test.
GGUF Quantization Levels Explained focuses on selecting among common GGUF artifacts. What Is LLM Quantization? provides a shorter introduction to rounding and memory.
Choose against a recorded baseline
Keep one higher-precision or trusted artifact as a reference. Run the same prompts, sampling settings, context, runtime revision, and hardware against each candidate. Record model-load memory, prompt speed, decode speed, and task-specific quality.
The best choice is usually the smallest artifact that preserves the behavior you need and runs efficiently on the available hardware. Bit count is an input to that decision, not the decision itself.