Attention: How Each Token Decides Which Other Tokens Matter
AI Foundations #11 follows tokenization and embeddings into attention: queries, keys, values, similarity scores, softmax weights, and context-dependent representations.
Approximately 6 min read · AI Foundations / Lesson 11
A token embedding gives the model a starting vector. Attention lets a position combine information from other allowed positions, producing a representation shaped by its context.
The same word can need different information
Consider these two sentences:
The bank approved my mortgage.
We sat on the bank of the river.
The token bank starts from a learned embedding associated with that token. But its useful meaning in the sentence depends on context.
In the first sentence, mortgage is highly informative. In the second, river is. In a causal language model, however, the earlier bank position cannot attend to those later words. A later position can use the earlier bank to build its own representation.
A model therefore needs a mechanism that can ask something like:
For this token, which other positions contain useful information, and how much should each one contribute?
Attention turns that question into matrix operations.
Three versions of each token: query, key, value
This terminology looked unnecessarily mysterious to me at first.
For each input vector, the attention layer creates three projected vectors:
Q = query
K = key
V = value
They are produced by learned weight matrices. In simplified form:
Q = XWq
K = XWk
V = XWv
where X contains the token representations and Wq, Wk, and Wv are learned parameters.
I find it easier to think about their jobs rather than their names.
A query represents what the current position is looking for.
A key represents what another position can be matched on.
A value contains the information that position can contribute if it receives attention.
The query and key decide how much to attend. The value supplies what information gets mixed in.
Query meets key
For one token to decide how relevant another token is, attention compares its query with the other token’s key.
The standard Transformer uses a dot product.
A larger compatible dot product generally means a larger attention score.
For a tiny imaginary example, suppose the later token mortgage compares its query with the keys at positions it can see. Treat these numbers as already-scaled scores:
The        0.2
bank       2.4
approved   1.1
my         0.3
mortgage   0.5
These are not probabilities yet. They are raw compatibility scores.
Here bank gets the largest score. At the later mortgage position, a causal decoder can draw on that earlier token without reading the future.
Why divide by the square root of dimension?
The Transformer paper defines scaled dot-product attention as:
Attention(Q, K, V) = softmax(QK^T / sqrt(d_k)) V
The sqrt(d_k) part puzzled me.
As the key/query dimension grows, dot products can grow in magnitude. Very large values can push softmax into extremely sharp regions, which makes optimization less well behaved.
Dividing by the square root of the key dimension keeps the score scale under better control.
This is why the operation is called scaled dot-product attention.
Softmax turns scores into weights
After computing the scaled scores, softmax converts them into non-negative weights that sum to 1 across the allowed positions.
Applying softmax to those five illustrative scaled scores gives approximately:
The         0.067
bank        0.604
approved    0.165
my          0.074
mortgage    0.090
These numbers are only an illustration, not values from a real model.
Now attention can take a weighted combination of the value vectors.
Conceptually:
new representation
= 0.067 × value(The)
+ 0.604 × value(bank)
+ 0.165 × value(approved)
+ 0.074 × value(my)
+ 0.090 × value(mortgage)
The output for mortgage now mixes value vectors from allowed earlier positions and itself. That is how context can change a representation without violating a causal mask.
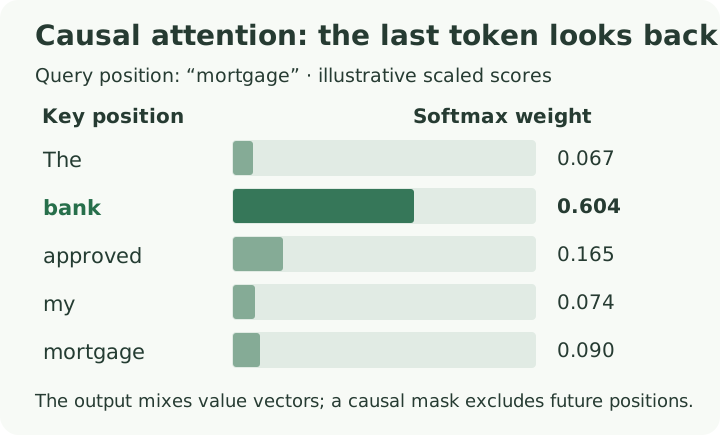
This is a worked numerical illustration. The scores are not measurements from a language model.
That is the key transition:
static token representation
-> attention over context
-> context-dependent representation
Attention does not literally retrieve words
The analogy can become misleading if I take it too literally.
The model is not running a database search for the word mortgage.
Queries, keys, and values are vectors learned during training. Their useful dimensions are not manually labeled with human concepts such as financial_word = true.
Training adjusts the projection matrices through the same machinery we already studied:
forward pass
-> loss
-> backpropagation
-> gradients
-> parameter updates
So the model learns attention patterns because they help reduce training loss.
The matrix view
Doing this token by token would be cumbersome. The elegant part is that the comparisons can be expressed with matrices.
If Q contains all query vectors and K contains all key vectors, then:
QK^T
produces a matrix of query-key scores.
Each row answers:
For this query position, how compatible is every key position?
After scaling, masking, and softmax, we get an attention-weight matrix. Multiplying it by V produces the weighted combinations for all positions.
This is one reason our earlier lessons on tensors and matrix multiplication mattered. Attention sounds linguistic when explained with sentences, but the implementation is tensor algebra.
Why masking matters for a language model
During next-token prediction, a causal language model must not look into the future.
If the training sequence is:
The cat sat on the mat
when computing the representation at sat, the model should not be allowed to use on the mat as future information for that prediction step.
A causal mask blocks attention to positions that come later in the sequence.
Conceptually the allowed pattern looks like:
position 1 -> 1
position 2 -> 1,2
position 3 -> 1,2,3
position 4 -> 1,2,3,4
The masked scores are excluded before the final attention weighting.
This small detail is fundamental to autoregressive language modeling.
One attention pattern is not enough
A sentence can contain many relationships at once.
One position may benefit from grammatical information. Another interaction may track a name, a previous object, punctuation, or something much harder to describe cleanly.
Transformers therefore use multiple attention heads.
Each head has its own learned projections and can form a different pattern of query-key compatibility.
Their outputs are combined so the layer can use several kinds of relationships in parallel.
I would not interpret each head as having one simple human-readable job. Some heads can show recognizable patterns, but the network is free to distribute computation across them.
Put attention inside the block
Attention mixes information across positions. A Transformer block also applies feed-forward computation, normalization, and residual connections. Positional information helps the attention calculation distinguish token order.
The Transformer lesson follows how these operations fit together.