What Is a KV Cache? How It Works and Why It Uses VRAM
Learn what an LLM KV cache stores, why it speeds up token generation, how to estimate its VRAM use, and how context length and quantization affect memory.
Approximately 4 min read
A KV cache stores attention keys and values for tokens a model has already processed. When the model generates the next token, it can reuse that state instead of recalculating every earlier token’s keys and values.
This makes autoregressive generation practical, but introduces a memory cost that grows with the amount of retained attention state. A long conversation can therefore consume much more memory than the same model answering a short question.
What gets reused
In transformer attention, queries compare against keys to determine how values are mixed. During decoding, the current token needs a new query and its own key and value. Earlier keys and values can be reused because those earlier positions have already been processed under the same causal history.
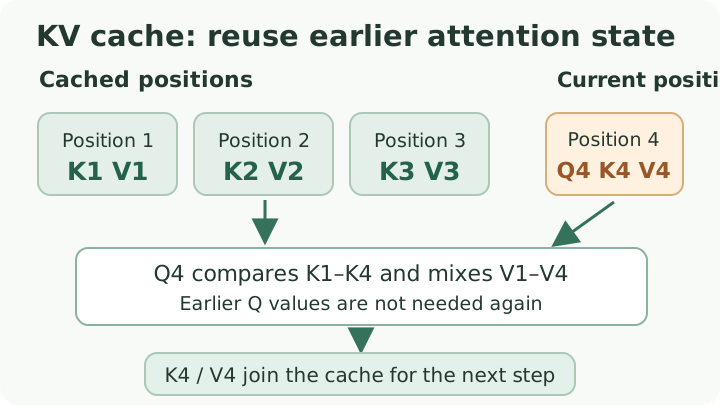
During decoding, past K/V pairs are reused; past queries need not be saved for this purpose.
Prefill processes the prompt and builds its cache. Decode then adds tokens incrementally. These phases have different shapes and performance characteristics: a fast prefill result does not automatically imply fast single-token generation.
The cache contains tensors rather than a plain-text chat log. It is still derived from the processed prompt and belongs within the application’s data-isolation boundary.
Calculate an example allocation
For a conventional full-attention transformer, a simplified estimate is:
KV bytes = 2 × layers × cached tokens × KV heads × head dimension × bytes per element.
Take a hypothetical configuration with 32 layers, eight KV heads, head dimension 128, 32,768 tokens and FP16 storage. The calculation is 2 × 32 × 32768 × 8 × 128 × 2 = 4,294,967,296 bytes, or 4 GiB for one sequence.
| Cached tokens | Example KV storage |
|---|---|
| 4,096 | 0.5 GiB |
| 8,192 | 1 GiB |
| 16,384 | 2 GiB |
| 32,768 | 4 GiB |
That allocation is separate from weights, compute buffers and runtime overhead. It explains how an 18 GiB weight set can leave a 24 GiB GPU with little room during a long request. See the VRAM planning guide for the full budget.
Architecture changes the calculation
Grouped-query attention lets several query heads share a smaller set of KV heads. Multi-query attention reduces the KV-head count further. Holding the other variables fixed, fewer KV heads mean less cached data.
Sliding-window attention can limit the retained history for some layers. Hybrid models may also maintain recurrent state alongside attention caches. Their allocations need to be read from the model and runtime rather than estimated using a full-attention formula for every layer.
The configured context limit and actual allocation are also different concepts. Some runtimes reserve a large cache at startup; others grow or manage a pool dynamically. Read initialization logs to see what your runtime allocated.
Cache precision and offload
Weight quantization and KV-cache quantization are separate choices. A Q4 weight file can run with an FP16 cache. A supported lower-precision cache can reduce memory, with quality and kernel-support trade-offs that should be tested on the intended workload.
llama.cpp exposes separate key and value cache controls, including --cache-type-k and --cache-type-v. Check the installed binary’s help for supported types and backend requirements. Cache offloading moves storage or work toward host memory, which can change latency and throughput.
If memory is tight, first test a context size that meets the actual task. Then compare cache precision or placement while holding the model, prompt and other settings fixed.
Serving several requests
Weights can be shared across requests, while each active sequence requires its own compatible state. Concurrency can therefore make cache capacity the limiting resource even when the model weights fit easily.
Paged allocation manages cache storage in smaller blocks. Prefix caching reuses state for matching prompt prefixes under the runtime’s sharing rules. These optimizations solve different problems: paging concerns allocation and fragmentation; prefix reuse concerns repeated computation.
For a failed startup, use the KV-cache allocation guide. For a conceptual continuation, AI Foundations #17 connects cache reuse to the generation loop.