Sampling: How Temperature, Top-k, and Top-p Choose the Next Token
AI Foundations #16 uses one probability distribution to show how greedy decoding, temperature, top-k, and top-p select the next token.
Approximately 4 min read · AI Foundations / Lesson 16
A language model does not write a whole answer in one operation. At each decode step it produces a logit for every token in its vocabulary. A decoding policy turns those scores into one selected token, appends it to the sequence, and asks the model for the next set of scores.
Temperature, top-k, and top-p act at this selection stage. They do not rewrite the model’s knowledge or change its weights.
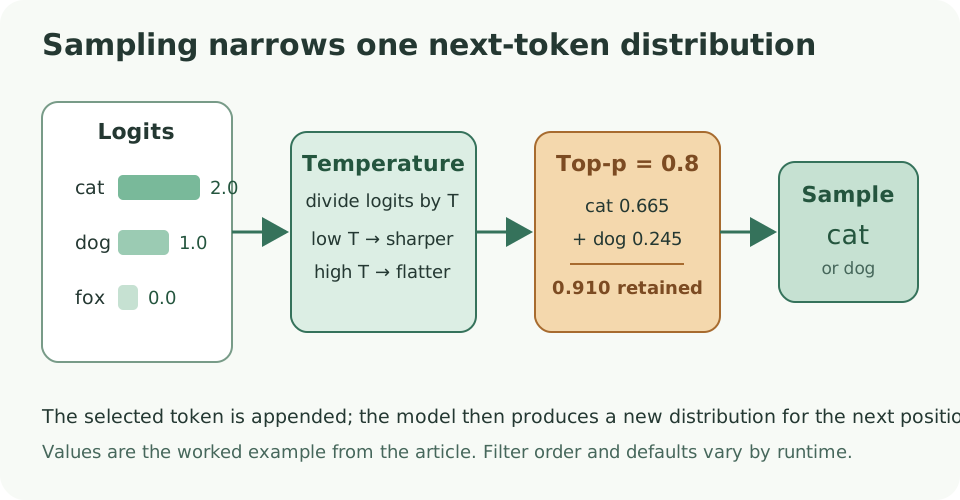
Sampling first reshapes or filters a next-token distribution, then selects one token from the candidates that remain.
Start with three logits
Assume a model assigns these logits to three possible continuations:
| Token | Logit |
|---|---|
cat |
2.0 |
dog |
1.0 |
fox |
0.0 |
Softmax exponentiates and normalizes the scores. Rounded to three decimals, the resulting probabilities are 0.665, 0.245, and 0.090. The order is unchanged, but the values now sum to one.
Greedy decoding always chooses cat because it has the largest probability. Sampling instead treats the probabilities as a distribution: cat is most likely, while dog and fox remain possible.
Temperature changes the shape of the distribution
Temperature divides the logits before softmax. With temperature T, the probability of token i is
pᵢ = exp(zᵢ / T) / Σⱼ exp(zⱼ / T)
For the same logits, a temperature of 0.5 produces approximately 0.867, 0.117, and 0.016. The leading token becomes much more dominant. A temperature of 2.0 produces approximately 0.506, 0.307, and 0.186, leaving more probability on the alternatives.
Temperature does not directly mean creativity. A flatter distribution increases variation, but the result still depends on the prompt, the model, and the rest of the decoding policy. Very high values can give weak candidates too much probability.
Temperature zero is commonly implemented as greedy or near-greedy decoding rather than literal division by zero. Check the runtime’s definition when exact reproducibility matters.
Top-k keeps a fixed number of candidates
Top-k retains the k highest-scoring tokens and removes the rest before sampling. With k = 2, the example keeps cat and dog; fox cannot be selected. The remaining probabilities are normalized again.
A fixed candidate count is easy to understand, but it ignores the shape of the distribution. Sometimes the model has one overwhelmingly likely continuation. Sometimes ten candidates are close. Top-k treats both situations with the same numerical limit.
Top-p keeps enough probability mass
Top-p, also called nucleus sampling, sorts tokens by probability and keeps the smallest leading set whose cumulative probability reaches a threshold p.
With the original probabilities and p = 0.8, cat alone contributes 0.665, which is not enough. Adding dog raises the cumulative mass to 0.910, so the candidate set becomes cat and dog. fox is excluded.
Unlike top-k, top-p can retain a small set when the distribution is confident and a larger set when probability is spread across many plausible tokens. The nucleus-sampling paper introduced this approach to avoid drawing from an unreliable long tail while keeping useful variation.
The controls can be combined
Many runtimes apply temperature, top-k, top-p, minimum-probability filters, repetition controls, and grammar constraints in a pipeline. The precise order and defaults are implementation details, so identical labels do not guarantee identical output across runtimes.
A practical starting point is to change one control at a time:
| Goal | Useful first comparison |
|---|---|
| Stable extraction or classification | Greedy or low temperature |
| General assistant response | Moderate temperature with a probability filter |
| Explore several phrasings | Increase temperature slightly or compare seeds |
| Stop implausible tail tokens | Use top-p, top-k, or a supported minimum-probability filter |
For an evaluation, record the complete sampling configuration. Reporting only temperature leaves out candidate filtering, repetition controls, stop conditions, and seed behavior.
A seed controls a random stream, not the whole system
When sampling uses a pseudorandom generator, a seed can help repeat the draws made by one software stack. The same seed does not guarantee identical text after a model file, runtime version, prompt formatting, kernel path, or sampling implementation changes.
Greedy decoding removes the sampling draw, but end-to-end determinism can still be affected by numerical differences and parallel execution. Treat reproducibility as a property of the recorded configuration, rather than of the seed alone.
Sampling happens inside a larger loop
After a token is selected, it becomes part of the next model input. The model then produces a new logit distribution conditioned on the expanded sequence. A small difference early in generation can therefore change every later distribution.
This is why sampling settings affect more than vocabulary variety. They choose the path the autoregressive process follows. Inference: What Happens After You Press Send explains the surrounding request loop; Context and KV Cache explains how the growing history is stored and reused.