How Much VRAM Do You Need for Local LLMs? 8B to 70B Guide
See which model sizes fit 8, 12, 16, 24, 48, and 80 GB GPUs, then account for quantization, KV cache, context length, and runtime overhead.
Approximately 6 min read
If you are choosing a GPU for local LLMs, start with the model size you actually want to run and the quantization you are willing to use. The parameter count alone is not enough.
For a single-user local setup with roughly 4-bit-class weights and moderate context, this is a useful first-pass map:
| GPU VRAM | Practical starting point |
|---|---|
| 8 GB | 7B–8B models; larger models usually need tighter quantization or CPU offload |
| 12 GB | 8B comfortably; many 12B–14B quantized models become realistic |
| 16 GB | 14B-class models with more room for context and cache |
| 24 GB | Many 30B–32B 4-bit-class models can fit, but context and runtime overhead matter |
| 48 GB | 70B 4-bit-class models become possible if the exact artifact and cache budget fit |
| 80 GB | Much more room for 70B models, larger caches, higher precision, or serving concurrency |
This is not a compatibility guarantee. The exact model file, architecture, runtime, context length, cache precision and number of active sequences decide whether a configuration really fits.
The fastest way to estimate VRAM
Use this order:
- Check the actual model artifact size.
- Add KV-cache memory for the context and concurrency you need.
- Leave room for compute buffers and runtime overhead.
- Check what else is already using the GPU.
- Validate with the exact runtime before buying hardware around the estimate.
If the model artifact itself nearly fills the card, the answer is already clear: the runtime has little room left for cache and working memory.
Weight storage: the quick math
A simple starting point is:
parameters × bits per weight ÷ 8
That gives an idealized weight-storage estimate:
| Parameters | FP16/BF16 | 8-bit | 4-bit |
|---|---|---|---|
| 7B | 14 GB | 7 GB | 3.5 GB |
| 8B | 16 GB | 8 GB | 4 GB |
| 14B | 28 GB | 14 GB | 7 GB |
| 32B | 64 GB | 32 GB | 16 GB |
| 70B | 140 GB | 70 GB | 35 GB |
Real quantized files are not exactly those sizes. Quantization metadata, scales and higher-precision tensors add overhead, so for GGUF and similar formats the actual file size is a better planning number than the nominal bit label.
Also keep units straight: 1 GiB = 1,073,741,824 bytes, while 1 GB = 1,000,000,000 bytes.
Why a model that “fits” can still run out of VRAM
Weights are only one part of the memory budget.
| Allocation | What drives it |
|---|---|
| Model weights | Artifact size, quantization and placement |
| KV cache | Context length, architecture, cache datatype and active sequences |
| Compute buffers | Runtime, batch shape, graph and backend |
| Runtime overhead | GPU context, libraries and captured graphs |
| Other applications | Display, browser, desktop apps and other GPU processes |
A 16 GiB model file on a 16 GiB GPU does not mean the workload fits. The runtime still needs memory after the weights are loaded.
KV cache is where long context starts to hurt
For a conventional full-attention transformer, a simplified KV estimate is:
2 × layers × cached tokens × KV heads × head dimension × bytes per element
The factor of two is for keys and values.
Grouped-query attention reduces the number of KV heads. Sliding-window, recurrent and hybrid architectures need architecture-specific accounting, so this formula is a planning tool rather than a universal calculator.
The important relationship is simple:
more cached tokens + more active sequences = more cache memory
That is why a model may run at 8K context but fail or lose headroom at 32K or 128K.
Example: why 24 GB can be enough at 8K but tight at 32K
Suppose a model’s weights occupy 18 GiB on the GPU.
For an illustrative cache using 32 layers, eight KV heads, head dimension 128 and FP16 storage for one sequence:
| Context | Example KV cache | Weights + cache |
|---|---|---|
| 4,096 | 0.5 GiB | 18.5 GiB |
| 8,192 | 1 GiB | 19 GiB |
| 16,384 | 2 GiB | 20 GiB |
| 32,768 | 4 GiB | 22 GiB |
At 32K context, a 24 GiB card has only about 2 GiB left before compute buffers, runtime overhead and other GPU processes.
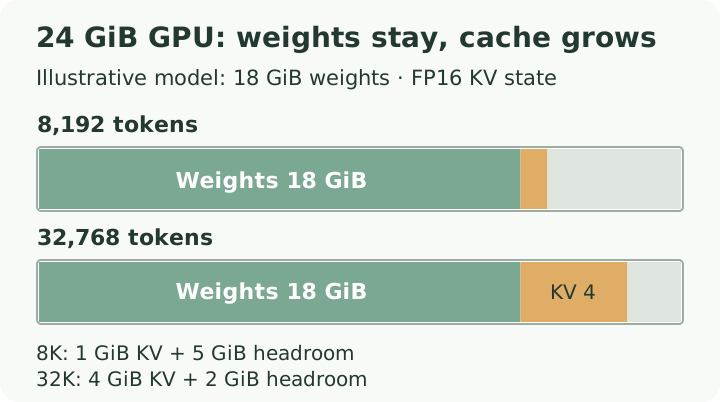
That is the practical reason not to size a GPU from model weights alone.
What each VRAM tier is good for
8 GB
Good for smaller local models and aggressive quantization. 7B–8B models are the obvious starting point.
You can run larger models with partial CPU offload, but “it launches” and “it is fast enough to use” are different questions.
12 GB
A useful tier for 8B-class models with more breathing room. Quantized 12B–14B models may also be practical depending on the artifact and context target.
This tier is much less forgiving if you want both a larger model and very long context.
16 GB
A strong fit for many 14B-class local workloads. It also gives smaller models more room for longer context, larger batches or other GPU applications.
For bigger models, the exact quantization determines whether you remain fully GPU-resident.
24 GB
This is where many 30B–32B quantized models become realistic on one consumer GPU.
A nominal 32B model at four bits starts around 16 GB for weights, but the exact file may be larger and the runtime still needs cache and working memory. Long context can consume the remaining headroom quickly.
48 GB
A 70B model at a nominal four bits starts around 35 GB for weights, which makes 48 GB an important threshold for single-GPU 70B-class experimentation.
Do not assume every 70B quantized artifact will fit with the context or concurrency you want. Check the actual file and cache budget.
80 GB and above
This tier gives far more room for 70B models at higher precision, larger KV caches, serving concurrency, or models whose real artifacts exceed simple four-bit estimates.
For production serving, memory capacity is only one part of the decision; throughput, latency and scheduling matter too.
Multi-GPU does not automatically behave like one giant GPU
Two 24 GB cards provide 48 GB of physical VRAM, but the runtime must explicitly place or split the model across them.
The result depends on the backend and split strategy. Inter-GPU communication can also affect performance.
Plan around the runtime’s actual placement behavior, not just the sum printed on the boxes.
Unified memory is different
On unified-memory systems, model memory and general system memory share a pool.
That can make large models possible without a separate VRAM ceiling, but the operating system and other applications still consume the same memory pool. Capacity does not guarantee GPU-like throughput.
Before buying a GPU, validate these five things
Use the exact model you care about, not only a parameter-count estimate.
- Artifact size: how large is the actual model file?
- Target context: do you need 8K, 32K, 128K or more?
- Concurrency: one interactive user or many simultaneous requests?
- Placement: will the whole model stay on the GPU?
- Speed: is the resulting configuration actually fast enough?
If you already own the hardware, load the exact artifact and inspect allocation logs before changing settings.
If VRAM is the limiting factor, continue with How to Reduce LLM VRAM Usage. If performance is the problem rather than capacity, use Local LLM Slow? Diagnose Prefill, Decode, GPU Offload, and Memory.