What Is a Tensor? The Shape of Data Inside AI
AI Foundations #4 explains tensor rank, shape, dtype, device, stride, element count, and memory through image and language-model examples.
Approximately 3 min read · AI Foundations / Lesson 04
A tensor is a multidimensional array of numbers. The useful questions are its shape, data type, device, and memory layout. Those properties tell a framework how to interpret the values and which operations can use them.
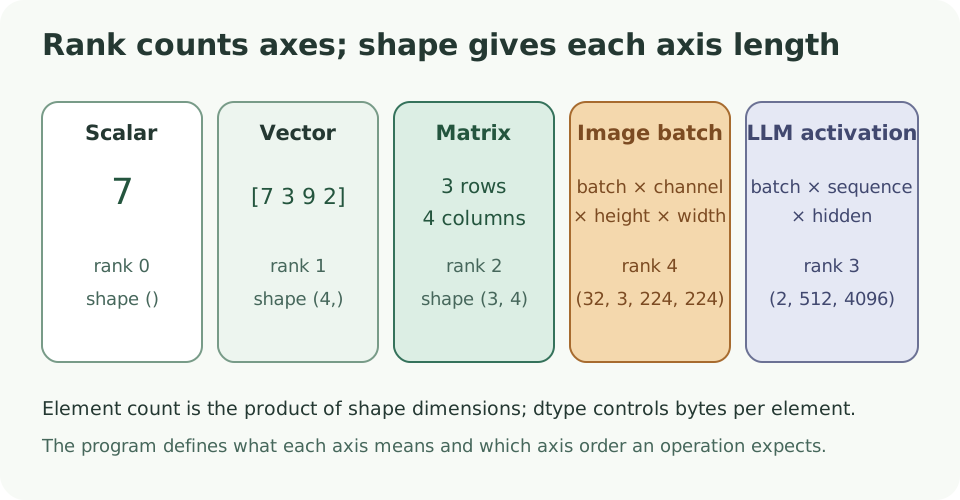
Rank counts axes. Shape gives the length of each axis. The meaning of an axis comes from the program and model architecture.
Rank and shape describe organization
A scalar such as 7 has no axes and can be represented as a rank-0 tensor. A list [7, 3, 9, 2] has one axis and shape (4,). Three rows with four values each form a rank-2 tensor with shape (3, 4).
Rank does not count elements. A tensor with shape (1000,) has one axis and 1,000 values. A tensor with shape (10, 10, 10) has three axes and also 1,000 values.
The element count is the product of the shape dimensions. This is the first memory calculation to perform when a tensor is unexpectedly large.
Axes need application-specific meanings
An RGB image can use shape (1080, 1920, 3), where the axes mean height, width, and color channel. A batch of 32 images in a channels-first framework can use (32, 3, 224, 224).
A language-model activation might use (batch, sequence, hidden). Shape (2, 512, 4096) then represents two sequences, 512 token positions, and 4,096 hidden features per position.
Frameworks can choose another axis order. Shape alone does not say which dimension is batch or channel; the operation’s contract supplies that meaning.
Dtype controls representation and memory
The data type determines how each element is represented. Common examples include FP32, FP16, BF16, integers, booleans, and specialized quantized formats.
The (2, 512, 4096) activation contains 4,194,304 elements. At two bytes per element, its raw payload is 8 MiB. At four bytes, it is 16 MiB. Shape is unchanged while memory doubles.
Quantized weight formats often need additional block scales or metadata, so their storage is not always exactly elements × nominal bits. Inspect the format rather than applying one byte count blindly.
Device says where the storage lives
A tensor can reside in system memory or accelerator memory. Moving a tensor from CPU to GPU changes its device and physical storage location, while its logical values and shape can remain the same.
Operations generally require compatible devices and data types. A CPU tensor and GPU tensor cannot simply participate in every operation without an explicit transfer. Those transfers can become a performance bottleneck when a model is divided across devices.
Shape and memory layout differ
Tensor libraries commonly describe storage using a shape, stride, and offset. Stride tells the runtime how far to move in underlying storage when an index advances along an axis.
A transpose can present the same stored values with different logical axes and strides. Some kernels accept that non-contiguous view; others require a contiguous copy. This is why two tensors with the same shape and dtype can still behave differently in performance or compatibility checks.
Weights, activations, and caches are all tensors
Neural-network weights are persistent learned tensors. Activations are intermediate tensors created for a particular input. A KV cache stores attention tensors retained across decode steps. Gradients and optimizer state add more tensors during training.
The word “tensor” does not identify the tensor’s job. Read its name, shape, dtype, device, and role in the computation graph.
The next lesson, What Is a Forward Pass?, follows input and parameter tensors through actual layer calculations.