Parameters, Weights, and Biases: What Are They in a Neural Network?
AI Foundations #3 counts the weights and biases in a small layer, shows how they change its output, and connects parameter count to model memory.
Approximately 3 min read · AI Foundations / Lesson 03
A parameter is a numerical value learned during training. In a neural network, most parameters are weights and biases stored in tensors. Parameter count measures how many learned values the model contains; it does not measure the size of every activation, cache, or runtime buffer used during execution.
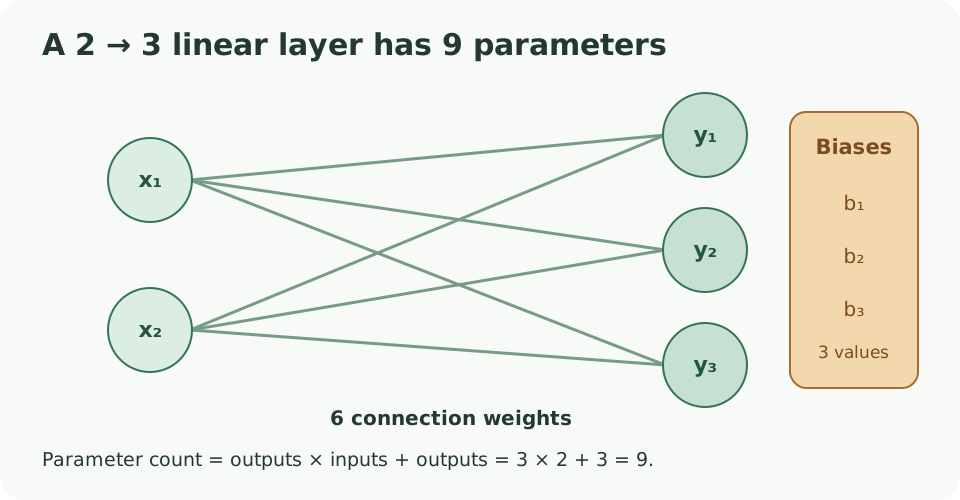
A fully connected layer with two inputs and three outputs has six weights plus three biases: nine trainable parameters.
Weights control contributions
For one output neuron with two input features, a linear calculation can be written as
y = w₁x₁ + w₂x₂ + b
With input [3, 5], weights [0.4, 0.2], and bias 0.5, the output is 3 × 0.4 + 5 × 0.2 + 0.5 = 2.7.
Changing the first weight to 0.04 changes the output to 1.62, even though the input is identical. A weight controls how strongly one input direction contributes to the calculation.
Bias shifts the result
The bias adds a learned offset. If both inputs are zero, the weighted terms disappear while the bias remains. That lets a layer represent relationships that are not forced through zero.
Weights and biases are both parameters because training can update them. Other architectures also contain learned embeddings, normalization values, convolution kernels, and specialized tensors. “Parameter” is the broader category.
Count a complete linear layer
A layer with I input features and O output features has a weight matrix with shape (O, I). With one bias per output, the parameter count is
parameter count = O × I + O
For two inputs and three outputs, the weight matrix contains 3 × 2 = 6 values and the bias vector contains 3, for a total of 9.
Deep networks repeat this pattern at larger scales and add other parameterized components. Transformer models contain embedding tables, attention projections, feed-forward matrices, normalization parameters, and an output projection. Architecture determines where the parameters live.
Parameter count and file size are related
If every parameter used two bytes, 7 billion parameters would require about 14 GB for raw values. Four-byte values would require about 28 GB. These decimal estimates exclude metadata and any mixed-precision tensors.
Quantization reduces the average storage used for many weight tensors. An idealized 4-bit payload for 7 billion values is 3.5 GB, though real artifacts also store scales, block metadata, alignment, and selected higher-precision data.
The checkpoint size is still not the total memory requirement. Inference needs activations, KV cache, temporary buffers, runtime state, and sometimes multiple loaded components. Training adds gradients and optimizer state.
Large parameter counts do not describe everything
Two models with the same parameter count can use different architectures, data, objectives, context mechanisms, and inference costs. Mixture-of-Experts models also separate total parameters from the subset active for one token.
Parameter count is useful for estimating storage and understanding capacity, but it is not a quality score. Evaluate a model on the target workload and record its actual artifact format and runtime configuration.
Parameters live inside tensors
Frameworks do not store billions of separately named variables. They organize learned values into tensors with defined shapes and data types. What Is a Tensor? shows how those shapes describe model weights, inputs, batches, and activations.