What Is a Forward Pass? How Data Moves Through a Neural Network
AI Foundations #5 calculates a complete two-layer forward pass and distinguishes parameters, activations, nonlinearities, inference, and training.
Approximately 3 min read · AI Foundations / Lesson 05
A forward pass applies a model’s current parameters to an input and calculates an output. Learning is not required for this step. Training and inference both use forward passes; training adds loss calculation, backpropagation, and parameter updates afterward.
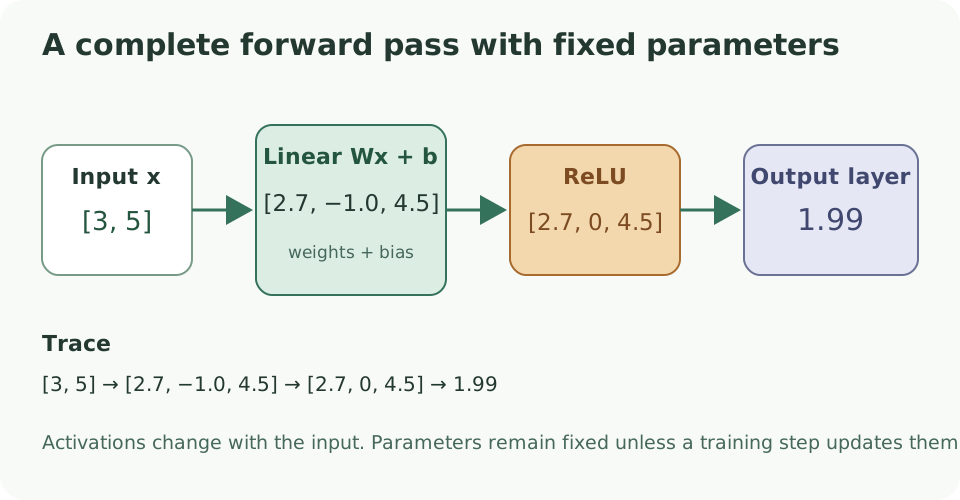
Every value in this diagram follows the worked calculation below. Activations change for the input; weights and biases are the stored parameters.
Calculate the first linear layer
Use input vector
x = [3, 5]
and a layer with three output units:
| Output unit | Weight on x₁ | Weight on x₂ | Bias |
|---|---|---|---|
| 1 | 0.4 | 0.2 | 0.5 |
| 2 | 0.1 | −0.3 | 0.2 |
| 3 | 0.7 | 0.5 | −0.1 |
The linear transformation Wx + b produces:
3 × 0.4 + 5 × 0.2 + 0.5 = 2.73 × 0.1 + 5 × -0.3 + 0.2 = -1.03 × 0.7 + 5 × 0.5 - 0.1 = 4.5
The layer has transformed two input features into three intermediate values: [2.7, -1.0, 4.5].
Apply a nonlinear activation
If every layer only performed a linear transformation, stacking the layers would still collapse into one linear transformation. Neural networks insert nonlinear functions so the complete model can represent nonlinear relationships.
ReLU applies max(0, x) element by element. It turns the first layer’s result into [2.7, 0, 4.5].
These intermediate values are activations. They depend on the current input. The weights and biases are parameters retained across inputs until training updates them.
Calculate the output layer
Use output weights [0.2, -0.1, 0.3] and bias 0.1. The final scalar is
2.7 × 0.2 + 0 × (−0.1) + 4.5 × 0.3 + 0.1 = 1.99
The forward pass is therefore a traceable chain:
[3, 5] → [2.7, -1.0, 4.5] → [2.7, 0, 4.5] → 1.99.
Changing an input changes the activations. Changing a weight changes the transformation. Changing the architecture changes which operations and parameter tensors participate.
Tensor shapes enforce the layer contract
The input has shape (2,). The first weight matrix has shape (3, 2), so it produces three outputs. Its bias has shape (3,). The second layer accepts those three activations and returns one output.
If a loaded tensor has the wrong shape, the multiplication cannot satisfy the layer contract. This is why runtime errors often report both expected and actual dimensions.
Forward and backward passes have different jobs
The forward pass produces predictions and intermediate activations. A loss function compares predictions with targets. Backpropagation then calculates how the loss changes with respect to each trainable parameter.
Training may retain forward activations because the backward pass needs them. Inference can often release intermediate values sooner because it does not calculate gradients. That is one reason training needs more memory than serving the same weights.
Large language models add embeddings, attention, normalization, residual connections, and repeated Transformer blocks, but they still execute a defined forward computation over tensors.
How Does a Neural Network Start Learning? adds a target and loss function to this calculation.