How Does a Neural Network Start Learning? Training Begins With Loss
AI Foundations #6 compares predictions with targets, calculates squared and absolute loss, aggregates a batch, and explains what loss can and cannot measure.
Approximately 3 min read · AI Foundations / Lesson 06
A forward pass produces a prediction. Training needs a numerical rule that compares that prediction with a target. A loss function supplies that rule, turning many individual errors into an objective the optimizer can reduce.
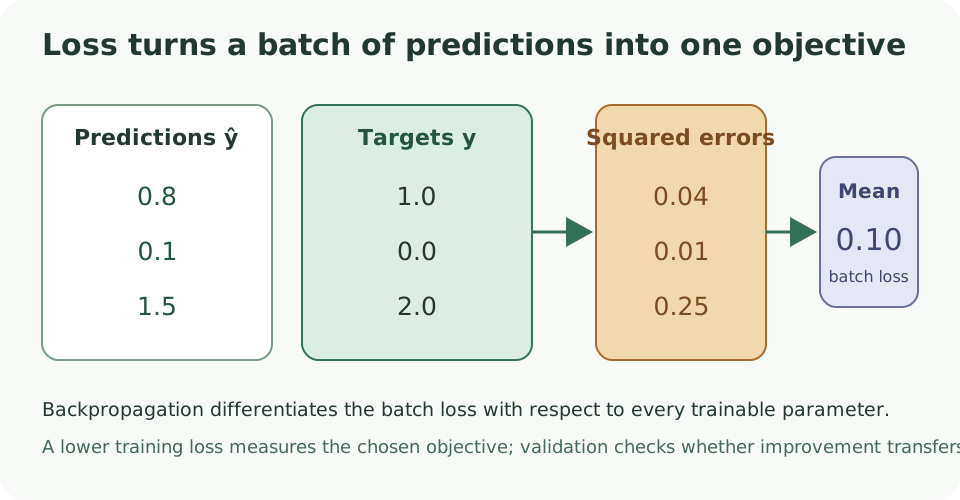
The loss function scores predictions under a chosen objective. Backpropagation differentiates the resulting batch loss with respect to model parameters.
One prediction can have several error measures
Suppose a regression model predicts 0.82 and the target is 1.00. The signed error is -0.18, but positive and negative errors would cancel if they were averaged directly.
Mean absolute error uses the error magnitude:
absolute error = |0.82 − 1.00| = 0.18
Squared error gives
squared error = (0.82 − 1.00)² = 0.0324
Both assign zero to an exact prediction, but they penalize larger errors differently. Squaring makes large deviations grow more quickly.
A batch produces one optimization objective
Training usually evaluates several examples together. For three targets [1.0, 0.0, 2.0] and predictions [0.8, 0.1, 1.5], squared errors are [0.04, 0.01, 0.25]. Their mean is 0.10.
Backpropagation starts from that aggregated scalar and applies the chain rule through the computation graph. The resulting gradients tell the optimizer how a small parameter change would affect the batch loss.
The batch size influences the estimate. A small batch can produce noisy gradients; a very large batch changes memory use and optimization behavior. Report it when comparing training runs.
Different tasks require different losses
Regression often uses squared or absolute-error variants. Classification commonly uses cross-entropy between target labels and predicted class probabilities. Language-model pretraining applies token-level cross-entropy to next-token predictions, usually while masking positions that should not contribute.
The loss must match the output and the task. Applying a convenient mathematical objective does not guarantee it captures every property users care about.
Training loss is not the final evaluation
A falling training loss shows that the model is fitting its training objective. It does not prove generalization to unseen data. Compare validation loss and task metrics on examples that did not drive parameter updates.
Loss can also hide subgroups and failure modes. One mean value may combine easy and difficult examples, short and long sequences, or different languages. Inspect distributions and task-specific errors when those distinctions matter.
For generation, a lower next-token loss does not automatically guarantee better factuality, instruction following, tool use, or human preference. Those properties require suitable evaluations.
Loss connects prediction to learning
The complete training step is:
- load a batch of inputs and targets;
- run the model’s forward pass;
- compute and aggregate loss;
- backpropagate parameter gradients;
- let the optimizer update parameters;
- clear or accumulate gradients according to the training plan.
The model begins the next step with slightly different parameter values. Repetition across many batches is what turns a fixed calculation into a trained model.
Gradient Descent follows the update itself, while Backpropagation shows how one loss supplies gradients to many earlier parameters.