What Does It Mean for a Machine to Learn?
AI Foundations #2 follows one parameter update to show how training data, a model, a loss function, gradients, and an optimizer create machine learning.
Approximately 3 min read · AI Foundations / Lesson 02
For a supervised machine-learning model, learning means changing numerical parameters so predictions improve under a defined loss function. The computer is not absorbing a lesson in the human sense. It is executing an optimization procedure.
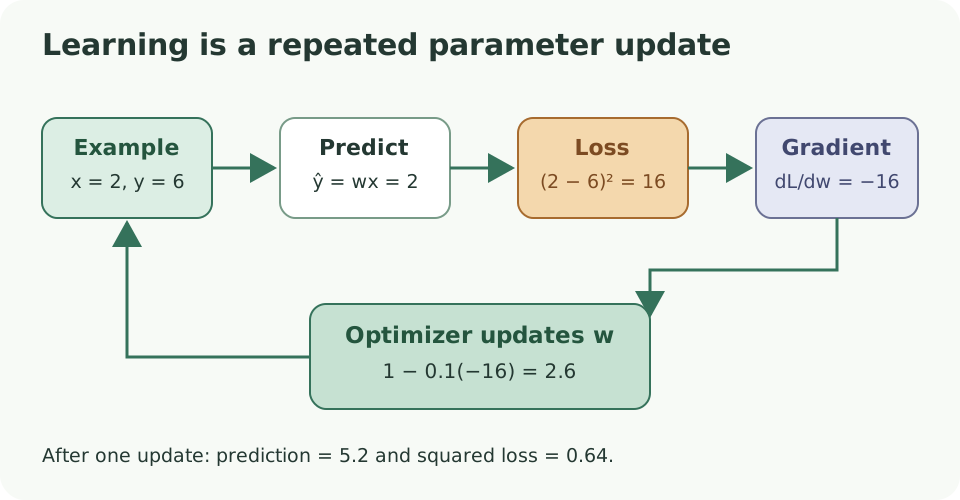
Training repeats a measurable cycle. Data supplies examples, loss scores the current prediction, and the optimizer changes parameters.
A model needs something it can change
Use the smallest possible model:
prediction ŷ = w × x
x is the input, w is a trainable parameter, and ŷ is the prediction. Suppose the training example is x = 2 with target y = 6. If the initial parameter is w = 1, the model predicts 2.
The model cannot improve unless the training process can measure the error and determine how changing w would affect it.
Loss turns quality into a number
Using squared error,
L = (prediction − target)²
the first prediction has loss (2 - 6)² = 16. The loss function defines what the optimizer is asked to reduce. A different task can use a different objective, such as cross-entropy for classification.
A low training loss means the model fits the measured training objective. It does not automatically mean the model is useful, fair, robust, or accurate on new data.
The gradient provides a direction
For this example, the derivative of loss with respect to w is
dL/dw = 2 × (w × x − y) × x
At w = 1, x = 2, and y = 6, the gradient is -16. A negative gradient says increasing w will reduce the loss locally.
With learning rate 0.1, one gradient-descent update is
w_new = 1 − 0.1 × (−16) = 2.6
The new prediction is 5.2, and the squared loss becomes 0.64. One update moved the model much closer to the target.
Real training uses many examples and parameters
Practical models contain many parameters and train on batches of examples. A training step usually performs four operations:
- run a forward pass to calculate predictions;
- aggregate a loss over the batch;
- backpropagate gradients through the computation graph;
- let an optimizer update the parameters.
This repeats across batches and training epochs. Optimizers such as SGD and Adam differ in how they turn gradient history into updates, but they still depend on an objective and calculated gradients.
Training data and evaluation data have different jobs
Training examples directly influence parameter updates. Validation data helps choose settings and detect overfitting. Test data estimates performance after development decisions are complete.
If the same examples guide training and final evaluation, the score can reward memorization. A model that predicts its training rows perfectly may still fail on new cases drawn from the intended use.
This is the difference between fitting and generalizing. Learning is useful when parameter changes capture patterns that transfer beyond the examples used to create them.
What ordinary inference does not do
After training, inference uses the fixed parameters to calculate an output for a new input. A chat request can change the active context and the generated answer without changing the weights.
Fine-tuning is additional training because it applies more parameter updates. Retrieval is different: an application finds external text and places it in the request. Prompting is also different: it changes the input to fixed parameters.
The next lesson, Parameters, Weights, and Biases, examines the numbers that training updates.