Inference: What Happens After You Press Send to a Trained Language Model
AI Foundations #15 follows one language-model request through tokenization, prefill, decoding, sampling, and the memory used along the way.
Approximately 5 min read · AI Foundations / Lesson 15
Language-model inference is the work a trained model performs after a request arrives. The weights already contain the result of training. Inference loads and uses those weights; it does not run backpropagation or update them for an ordinary chat request.
That distinction explains the whole request path. Text must become tokens, the model must turn those tokens into next-token scores, a decoding rule must select one continuation, and the process repeats until it reaches a stopping condition.
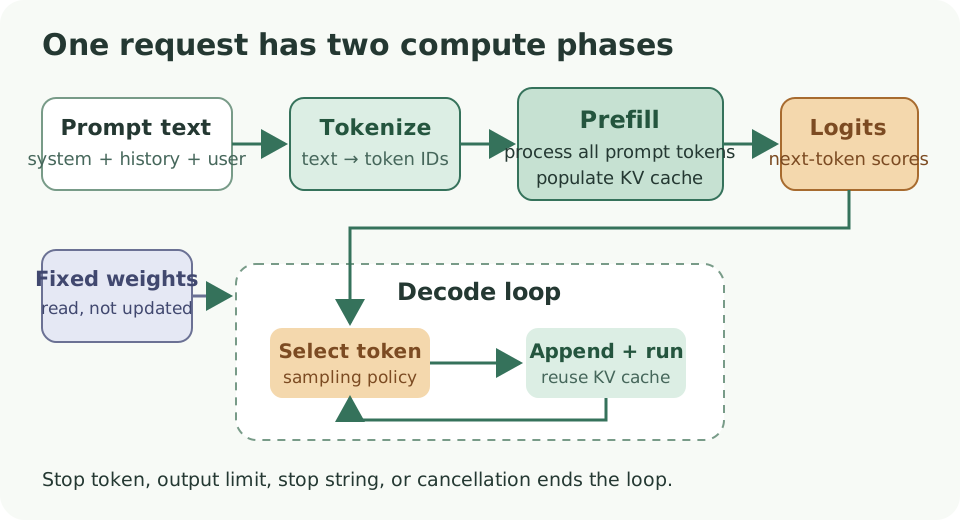
Inference has a one-time prompt phase followed by a repeated one-token decode loop. The model weights are read throughout but remain unchanged.
From text to model input
Suppose the request is The capital of France is. A tokenizer converts that string into token IDs from the model’s vocabulary. Tokens are not guaranteed to match words: a common word may be one token, while a rare name or piece of code may be several.
The application also adds material the user may not see directly. A chat request can include a system message, role markers, tool definitions, retrieved documents, earlier conversation turns, and formatting tokens. All of these consume input context when they are sent to the model.
Each token ID selects an embedding vector. Positional information is added so the network can distinguish the same token at different places in the sequence. Those vectors then pass through the model’s Transformer blocks.
Prefill processes the prompt
The initial pass over the input is commonly called prefill. The model processes the prompt positions and produces hidden representations. At the final position, the output layer produces one score for every vocabulary token. These raw scores are logits.
If the vocabulary has 100,000 entries, the final logit vector has 100,000 entries. A high logit means the model currently favors that token relative to the alternatives; it is not yet a normalized probability.
The prefill phase can evaluate many prompt positions in parallel. This is why prompt-processing speed is reported separately from generation speed. A long document increases prefill work even if the requested answer is short.
Decoding generates one token at a time
A decoding rule converts the final-position logits into a selected token. Greedy decoding chooses the largest score. Sampling can apply temperature, top-k, top-p, or other controls before drawing a token.
After one token is chosen, it is appended to the sequence. The model then calculates the scores for the following token. Autoregressive generation therefore follows this loop:
- calculate logits for the next position;
- select one token;
- append it to the active sequence;
- stop or repeat.
The loop ends when the model emits a configured stop token, the application finds a stop string, the output limit is reached, or another runtime condition ends the request.
Decode is sequential: token 20 depends on the preceding 19 generated tokens. Hardware can perform the matrix operations within a step in parallel, and a server can batch several requests, but one request cannot normally choose all of its future tokens at once.
The KV cache avoids repeating earlier attention work
During attention, each layer calculates keys and values for the active token positions. Once the prompt has been processed, those earlier keys and values can be stored in a KV cache.
At the next decode step, the model calculates new state for the latest token and attends to the stored history. It does not need to rebuild every earlier key and value from scratch. The cache grows as the sequence grows, which saves computation while consuming memory.
This is why the model’s weights are only one part of an inference memory budget. A real deployment also needs space for the KV cache, temporary compute buffers, runtime overhead, and any concurrent requests. Context and KV Cache follows that lifecycle in detail.
What remains fixed and what changes
The trained parameters remain fixed during ordinary inference. The input tokens, activations, KV cache, logits, and sampled continuation change for each request.
This separation helps diagnose several common misunderstandings:
| Observation | What changed |
|---|---|
| A different prompt produces a different answer | Input context |
| The same prompt varies with temperature or seed | Token selection |
| A longer chat uses more memory | Active sequence and KV cache |
| Fine-tuning changes later answers | Model parameters |
A chat application’s saved memory is also usually outside the model. The application may retrieve stored notes and insert them into a later prompt. The model can use those tokens during inference without having learned them into its weights.
Measure the stages separately
One speed number hides useful information. Time to first token includes request preparation, queueing, tokenization, prefill, and the first decode step. Inter-token latency describes the delay between generated tokens. Output throughput reports generated tokens per second. Prompt-processing throughput describes prefill.
These measurements answer different questions. A long prompt can have slow time to first token and fast generation afterward. A short prompt can start quickly but decode slowly because the model is large or poorly placed across devices. A busy server can add queue delay even when the model itself is fast.
When comparing two inference setups, keep the model artifact, prompt, output length, sampling settings, context state, and concurrency consistent. Otherwise a faster result may come from a different workload rather than a better runtime.
Where the next lesson begins
Inference produces logits, but logits do not decide the continuation by themselves. The application still needs a decoding policy. Sampling: How Temperature, Top-k, and Top-p Choose the Next Token works through that decision with concrete numbers.