What Is LLM Quantization? FP16, INT8 and INT4 Explained
Learn how LLM quantization reduces model memory, what FP16, INT8 and INT4 mean, and how GGUF, AWQ, GPTQ, scales, groups, and quality trade-offs work.
Approximately 4 min read
LLM quantization stores model numbers using a lower-precision representation. The main attraction for local inference is memory: reducing the bytes needed for weights can make a model fit on hardware that could not hold its original checkpoint.
The cost is approximation. A quantized weight usually reconstructs a nearby value rather than the exact original number. A useful quantization preserves the behaviour you need while reducing memory or improving execution on the intended runtime.
Start with the memory calculation
For weights alone, an idealized estimate is parameters × bits per weight / 8.
| Representation | Nominal bytes per weight | Idealized 8B weight storage |
|---|---|---|
| FP32 | 4 | 32 GB |
| FP16 or BF16 | 2 | 16 GB |
| INT8 | 1 | 8 GB |
| INT4 | 0.5 | 4 GB |
These are decimal GB and exclude scales, metadata and tensors kept at higher precision. Inference also needs KV cache, temporary buffers and runtime memory. A four-bit filename therefore does not guarantee exactly half a byte per parameter or a particular GPU fit.
FP16 and BF16 are floating-point formats with different exponent and precision layouts. In local-model discussions, “quantized” usually refers to a further reduction into low-bit inference formats, rather than merely storing a checkpoint in 16-bit floating point.
Quantization in one numerical example
Choose a scale of 0.1. To encode a weight of 0.37, divide by the scale and round: round(0.37 / 0.1) = 4. Reconstructing gives 4 × 0.1 = 0.40, an error of +0.03.
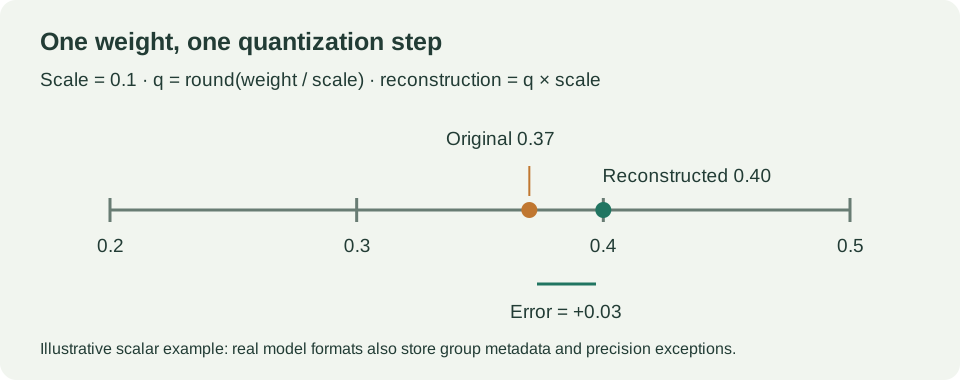
Real schemes choose how to represent groups of weights, where to spend precision and how to limit harmful errors. A scale may belong to a tensor, channel or block. An asymmetric scheme can also use an offset or zero point. The grouping and auxiliary data contribute to the effective bits per weight.
Which numbers are compressed?
Weight-only quantization compresses stored model parameters. Weight-and-activation quantization also changes representations used for intermediate computations. KV-cache quantization applies to attention state accumulated while processing a request.
These choices are related but separate. Loading Q4 weights does not automatically make the KV cache four-bit. A kernel may also load compressed weights and compute in a different precision. The hardware and runtime determine which combinations are supported efficiently.
Post-training quantization converts an already trained model. Quantization-aware training exposes training to quantization effects so the model can adapt. Both aim to manage approximation error, but they operate at different points in the model’s development.
Methods, formats and calibration
GGUF is a container format used in the GGML ecosystem. Labels such as Q4_K_M describe quantization choices inside it. AWQ and GPTQ are quantization methods commonly encountered in GPU-serving workflows. Choose a runtime-compatible artifact before comparing filenames.
Calibration data helps some methods identify sensitive weights or activation patterns. In llama.cpp workflows, an importance matrix can guide precision allocation. Its usefulness depends on the model, quantization recipe and calibration coverage. A filename alone does not tell you how carefully a conversion was made.
Start from a high-quality source checkpoint when making a new quant. Requantizing an already lossy artifact cannot recover information discarded by the earlier conversion. Preserve the source model, revision, conversion tool and recipe so later comparisons have a clear reference.
Memory savings and speed are different results
A smaller artifact may become much faster if it changes the deployment from CPU/GPU offload to full GPU residency. Within a configuration that already fits, performance depends on kernels, memory traffic, batch size and model architecture. Lower bit width does not by itself predict prompt-processing or decode speed.
Measure those phases separately. Keep model, context, workload and runtime fixed when comparing quantizations. If one run also changes GPU placement or the amount of context, the result answers a broader deployment question rather than isolating numerical precision.
Choose using your tasks
Begin with a quantization that fits comfortably and has good runtime support. Test the work you actually care about: code changes, extraction, reasoning, tool arguments or conversation. Keep a higher-precision reference where practical and compare more than one prompt.
Perplexity can reveal distributional changes, while task tests show whether those changes matter to your application. Neither a single amusing answer nor a tiny numerical difference settles every use case.
For interpreting downloadable filenames and choosing between Q4, Q5, Q6 and Q8, continue with GGUF Quantization Levels Explained. For a worked quantize/dequantize calculation across several weights, see AI Foundations #18.