GGUF Quantization Levels Explained: Q4, Q5, Q6 and Q8
Learn what GGUF quantization labels such as Q4_K_M, Q5_K_M, Q6_K and Q8_0 mean, how they affect model size, quality, RAM, VRAM, and speed.
Approximately 4 min read
A GGUF filename tells you which model artifact you are downloading and gives clues about its precision. It does not, by itself, tell you whether that file will fit your workload or outperform another conversion.
Use the label to narrow the candidates, then check the actual file size, source model, conversion details and runtime support. This guide focuses on those deployment decisions. The numerical mechanism is covered in What Is LLM Quantization?.
Read the label in context
GGUF is a model container. A label such as Q4_K_M describes a quantization recipe for tensors stored inside it. The four indicates a low-bit family; scales, block metadata and mixed tensor choices mean the whole file can use more than four effective bits per weight.
The K family uses block-based quantization structures. S and M identify different recipes within a family. They should not be read as guarantees of “small quality” and “medium quality,” or compared as universal scores across unrelated models.
| Label | Useful interpretation |
|---|---|
| Q4_0 | An older four-bit block format; distinct from Q4_K recipes |
| Q4_K_S | A smaller K-family four-bit recipe |
| Q4_K_M | A commonly used mixed recipe balancing size and fidelity |
| Q5_K_S / Q5_K_M | Higher-precision K-family choices with different tensor allocations |
| Q6_K | A higher-precision option when memory permits |
| Q8_0 | An eight-bit quantized representation, still an approximation |
IQ formats and lower-bit Q2/Q3 variants extend the choices further. Their value depends on model sensitivity and backend support. Begin with the runtime’s supported types and the artifact’s conversion notes.
Use the real file size
The llama.cpp quantization documentation gives an illustrative Llama 3.1 8B comparison:
| Artifact | Example size |
|---|---|
| Q4_K_S | 4.36 GiB |
| Q4_K_M | 4.58 GiB |
| Q5_K_S | 5.21 GiB |
| Q5_K_M | 5.33 GiB |
| Q6_K | 6.14 GiB |
| Q8_0 | 7.95 GiB |
| F16 | 14.96 GiB |
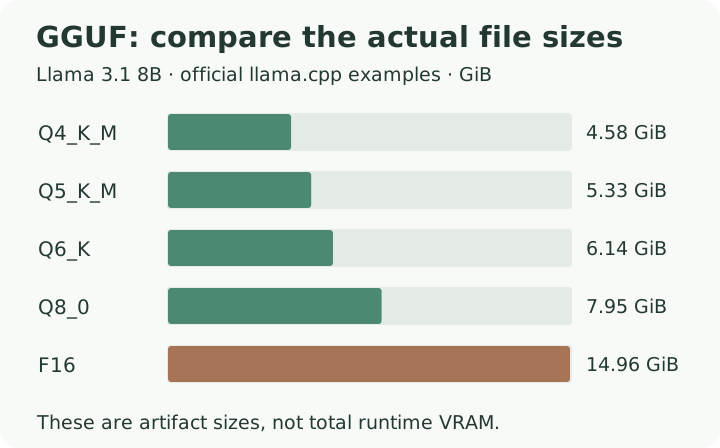
These are file sizes for a single model, as reported in the llama.cpp quantization documentation, not runtime memory use or quality rankings.
Treat this as one model’s example. Vocabulary size, architecture, expert tensors and precision exceptions change the ratio. For a download decision, use the size of the exact file or complete set of shards.
The file also needs somewhere to live at runtime. Full GPU placement requires room for the weights plus cache and working buffers. Partial CPU offload can run a larger file, but changes its performance characteristics.
A 24 GB GPU choice
Suppose one model has a 19 GB Q4 artifact and a 22 GB Q5 artifact. Both are smaller than 24 GB on disk, yet the Q5 leaves much less space for context and runtime allocations.
If the Q5 forces weights back into host RAM, the Q4 may offer a better deployment even before evaluating answer quality. If both fit with your real context and concurrency, compare output quality and speed directly. This example is a memory-planning exercise; the exact budget comes from the model and runtime logs.
Keep decimal GB and binary GiB consistent when doing the calculation. For the full allocation breakdown, use the VRAM planning guide.
Check how the artifact was made
Useful conversion information includes the source repository and revision, tokenizer and chat template, conversion-tool revision, tensor-specific precision choices, and whether calibration or an importance matrix was used.
An imatrix collects importance information from calibration text and can guide quantization decisions. It is one part of a recipe, not a universal quality certificate. A strong result still needs a relevant test against another artifact under matched conditions.
Prefer a direct conversion from a good source checkpoint. Requantization compounds an existing approximation. Two files with the same Q4_K_M label can differ because their source checkpoints, tool versions or precision policies differ.
Compare candidates without moving the goalposts
Download two neighbouring choices only when you have a reason to compare them. Keep the base model, prompt set, chat template, context, cache precision, offload and runtime fixed. Record prompt-processing and generation speeds separately.
First confirm that each artifact loads and produces coherent output. Then test the tasks that would make you reject a quant: incorrect extraction, broken code, tool-argument mistakes or reasoning failures. Use several examples, and inspect failures rather than relying on one aggregate number.
Choose the smallest candidate that meets your quality needs and runs comfortably within the intended memory budget. Keep the evaluation notes with the artifact so a later runtime upgrade can be checked against the same baseline.