Speech-to-Text vs Text-to-Speech: What's the Difference?
Learn the difference between speech-to-text and text-to-speech, how ASR and TTS models work, key accuracy metrics, streaming, voice cloning, and local AI use.
Approximately 4 min read
Speech-to-text turns an audio signal into written words. Text-to-speech turns written words into an audio signal. A voice assistant often uses both, with an application or language model between them to decide what to say.
The direction of that conversion determines the model’s job, the data it needs and how you should evaluate its output.
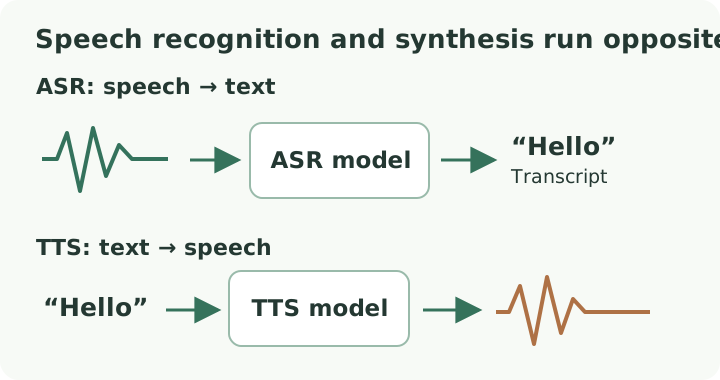
ASR is evaluated against the intended words; TTS also needs listening checks for pronunciation and naturalness.
Choose the component by its output
| Task | Input | Output | Typical use |
|---|---|---|---|
| Speech-to-text, also called ASR | Recorded or live audio | Transcript | Dictation, captions, meeting notes |
| Text-to-speech, or TTS | Text, sometimes with voice conditioning | Spoken audio | Narration, accessibility, spoken responses |
| Speaker diarization | Audio with one or more speakers | Speaker-labelled time spans | Separating participants in a meeting |
| Voice conversion | Speech | Speech with changed voice characteristics | Changing speaker identity while retaining spoken content |
Transcribing a meeting does not require a chatbot. Narrating a document does not require a chatbot either. Add a language model when the application needs to summarize, answer, translate text or otherwise transform the content.
How recognition and synthesis differ
An ASR system receives a waveform or an acoustic representation such as a spectrogram and predicts text. Whisper, for example, uses an audio encoder and an autoregressive text decoder. Noise, clipping, accents, overlapping speech and unfamiliar names can all affect the transcript.
A TTS system must choose a spoken realization of text. The sentence “You’re here” can sound relieved, surprised or annoyed. Pronunciation, pace, pauses and intonation are all part of producing the waveform.
Traditional neural TTS pipelines separate text processing, acoustic prediction and waveform synthesis with a vocoder. Other systems combine these stages more tightly. Text normalization matters in either case: “$12.50”, a date and a product code may each require a different spoken form.
Voice cloning conditions generation on a reference voice or speaker representation. The model generates new speech; it is not simply replaying the reference recording. Whether it preserves speaker identity, pronunciation and natural rhythm must be evaluated separately.
Calculate a recognition error rate
Word Error Rate is:
WER = (substitutions + deletions + insertions) / reference words.
Consider this pair:
| Reference | Recognized text |
|---|---|
| the cat sat on the mat | the cat sits on mat |
There are six reference words. Replacing sat with sits counts as one substitution. Omitting the second the counts as one deletion. There are no insertions, so WER is (1 + 1 + 0) / 6 = 0.333, or about 33.3%.
Insertions can make WER exceed 100%. A perfect word match has WER zero, but a transcript can still need punctuation, capitalization or timing edits. Use the same reference and normalization rules when comparing two systems.
Evaluate synthesized speech by listening and measuring
TTS quality has several dimensions. A voice may sound natural while mispronouncing a name; it may resemble the reference speaker while introducing long pauses. Keep a short evaluation script containing ordinary sentences, numbers, abbreviations, questions and domain-specific words.
| Check | What to listen for |
|---|---|
| Intelligibility | Every intended word is understandable |
| Pronunciation | Names, numbers and technical terms are spoken correctly |
| Prosody | Pauses, emphasis and intonation fit the sentence |
| Voice consistency | Speaker characteristics remain stable across passages |
| Audio quality | No clicks, clipping, abrupt cuts or distracting noise |
Keep output volume comparable when listening. A louder sample can seem more impressive without being more accurate or natural.
Throughput and conversational delay
Real-time factor compares processing time with audio duration. A system that processes 60 seconds of audio in 15 seconds has an RTF of 15 / 60 = 0.25. That is faster than real time, yet a user could still wait several seconds before the first result appears.
For recognition, measure the delay until useful text and whether earlier words are revised. For synthesis, measure time to first audio and whether playback can continue without gaps. End-to-end voice response time also includes endpoint detection, text processing, application work and audio buffering.
Put the pieces together
A modular voice assistant follows this sequence: microphone audio → optional voice activity detection → ASR → application or LLM → TTS → playback. Each boundary needs a useful representation: audio chunks, text, structured actions or synthesized samples.
Start by testing recognition and synthesis independently. A known recording checks ASR. A fixed text passage checks TTS. Once both are dependable, connect the loop and measure the full delay. This makes it much easier to locate a bad transcript, an incorrect answer or a slow voice response.
For the recognition stage in more detail, read How Whisper Works.