How Does Whisper Work? Speech Recognition Explained
Learn how OpenAI Whisper turns audio into text using log-Mel spectrograms, encoder-decoder Transformers, language tokens, timestamps, and autoregressive decoding.
Approximately 4 min read
Whisper turns recorded speech into text using an audio encoder and a text decoder. The encoder processes a time-frequency representation of the recording. The decoder uses that representation to predict text and task-related tokens, including timestamps.
Following one recording through those stages explains both its strengths and its common failures: a noisy microphone affects the input, an incorrect language choice affects decoding, and text carried from an earlier segment can influence what appears next.
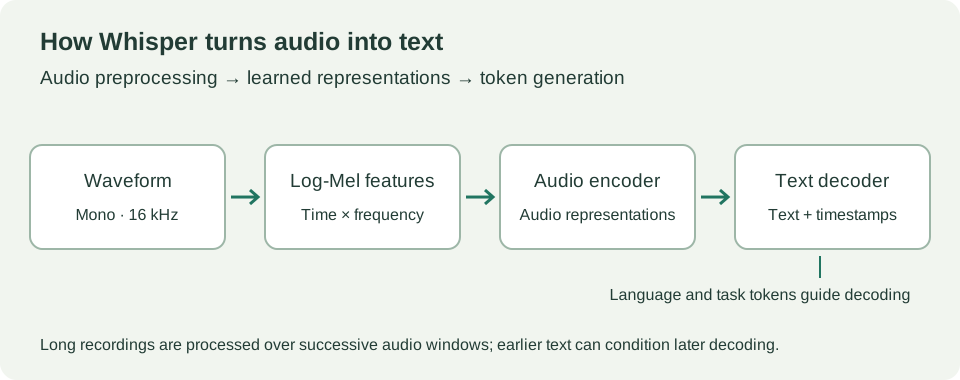
From a recording to a log-Mel spectrogram
The official audio loader converts input to mono and resamples it to 16 kHz when necessary. One second then contains 16,000 samples; 30 seconds contains 480,000. A recording made at 44.1 or 48 kHz can still be used because the loader handles resampling.
The waveform describes amplitude over time. Preprocessing transforms short portions into frequency information and groups it on a Mel scale. Applying logarithmic scaling produces the log-Mel spectrogram used by the model. Time runs along one axis and frequency bands along the other.
This representation makes changing speech patterns easier for a neural network to process. It also carries problems in the original audio: clipping, competing speakers, music and weak speech remain part of the signal. Increasing the model size cannot restore information that the microphone failed to capture.
The encoder and decoder
The audio encoder transforms the spectrogram into learned representations. The decoder attends to those representations and generates one token after another, using both the audio and previously generated tokens.
Special tokens specify parts of the task, including language, transcription or translation, and timestamp behaviour. Transcription keeps the spoken language. Whisper’s speech-translation task produces English text from supported speech in other languages.
Because generation is probabilistic, plausible text can appear even when the audio evidence is weak. Silence, background sounds and repeated context can contribute to hallucinations. For a technical recording, names, abbreviations and uncommon vocabulary deserve particular attention during review.
How long recordings are processed
The original transcription implementation works through audio using roughly 30-second windows. Timestamps help decide how far the process advances, so transcription is more involved than cutting a file into unrelated chunks and joining their outputs.
Earlier text can condition the next window. This often helps continuity, but it can also carry an error forward. If repeated phrases accumulate, inspect the audio around the first repetition and compare behaviour with previous-text conditioning changed.
The decoder can use temperature fallback and checks such as compression ratio, average log probability and no-speech probability. These are useful signals for identifying suspect segments. They do not replace listening to the recording.
Timestamps, speakers and streaming
| Output or feature | What to expect |
|---|---|
| Segment timestamps | Approximate boundaries for a span of transcribed speech |
| Word timestamps | More detailed alignment estimates when requested and supported |
| Speaker labels | A separate diarization task; ordinary Whisper transcription does not assign reliable speaker identities |
| Streaming | Requires an application to manage chunks, overlap and revisions around the model |
Timestamp tokens use a discrete time resolution. The resulting boundaries should be checked before treating them as finished subtitles. Very small streaming chunks can remove useful context and force frequent reprocessing; throughput on an hour-long file says little about the delay of an interactive voice interface.
Run a first transcription
The official repository documents installation, supported models and FFmpeg requirements. After installing the package, a CLI transcription can be started with:
whisper recording.wav --model small --task transcribe
The Python interface exposes the same basic workflow:
import whisper

model = whisper.load_model("small")
result = model.transcribe("recording.wav")
print(result["text"])
for segment in result["segments"]:
    print(segment["start"], segment["end"], segment["text"])
Use a short recording with a known transcript first. Keep the model, language, decoding options and runtime recorded when comparing speed or accuracy. Larger models usually demand more memory and computation; choose using your recordings and hardware rather than a single ranking.
Check the transcript where errors matter
Word Error Rate measures substitutions, deletions and insertions against a reference transcript. It is useful for comparing systems on the same audio, but punctuation, timestamps, speaker attribution and rare technical terms may need separate checks. Character Error Rate can be useful when word segmentation is less suitable.
For a meeting, inspect names, decisions and numbers. For subtitles, inspect timing and line breaks. For a voice assistant, measure time to the first usable text as well as total processing time. These tasks share an ASR model but have different acceptance criteria.
The Whisper model card describes known limitations and evaluation context. Use those alongside a small reference set from the kind of audio you actually need to transcribe.