How Does AI Video Generation Work? Text-to-Video vs Image-to-Video
Learn how AI video generators create motion from text or images, including latent video, temporal consistency, diffusion transformers, frames, seeds, and camera control.
Approximately 4 min read
AI video generation must create frames that look plausible and belong to the same moving scene. A red car should keep its shape and colour as it crosses the screen; the background should move consistently with the camera.
That requirement, called temporal consistency, is what makes video more than a sequence of independently generated images. Modern systems model relationships across time alongside visual appearance.
Text-to-video or image-to-video?
| Choice | Starting information | Useful when |
|---|---|---|
| Text-to-video | A written scene description | You want the model to invent composition and appearance |
| Image-to-video | A starting visual, usually with text | You need stronger control over the first frame or subject appearance |
| Video-to-video | An existing sequence plus conditioning | You want to transform footage while retaining some structure |
Text-to-video gives the model many decisions: objects, framing, lighting and motion. Image-to-video fixes more of the starting appearance, but later frames still require new content. A camera rotation can reveal a person’s back or an unseen part of a room, which the model has to synthesize.
Represent space and time together
Many video generators extend diffusion or related generative techniques into a representation with a temporal dimension. Latent video reduces the size of this representation. A decoder later turns it into visible frames.
Video diffusion transformers can process spacetime patches: pieces of a representation that cover spatial and temporal information. Attention and other temporal mechanisms let different positions exchange information, helping maintain objects and motion across frames.
The exact architecture varies. What matters for interpreting an output is that the model must coordinate appearance, changing pose, occlusion, camera movement and lighting. A coherent first frame only solves part of that task.
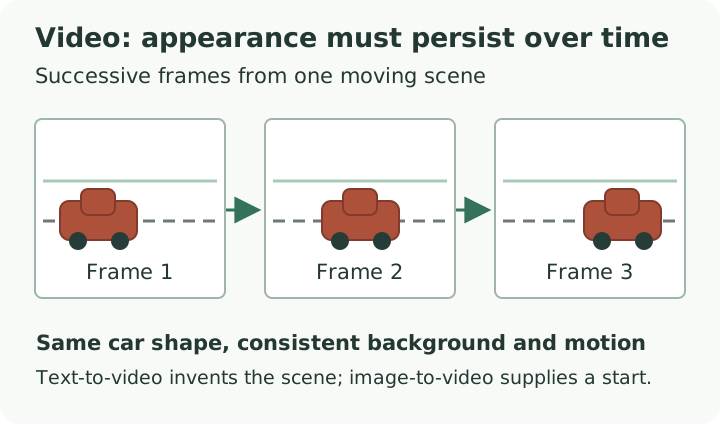
Maintaining the car and background across frames is the temporal problem; producing three attractive independent images would not guarantee this continuity.
Frames, duration and playback speed
A five-second clip at 16 frames per second contains 80 displayed frames. Increasing the playback frame rate of the same frames changes playback duration or requires additional frames; it does not automatically create better motion.
Interpolation can synthesize intermediate frames, but it cannot reliably repair an object that changed identity during generation. Evaluate the original motion before using interpolation or upscaling to polish the result.
Longer duration and higher resolution increase the represented workload and usually increase memory and generation time. Architecture, temporal compression and runtime settings affect the exact scaling. Compare clips with matched dimensions, frame counts and model settings when measuring speed.
Write a shot the model can follow
Separate subject motion from camera motion. “The boat moves left while the camera remains fixed” defines a different shot from “the camera tracks the boat.” Combining several dramatic actions in a short clip makes the intended trajectory ambiguous.
For image-to-video, try a bounded instruction such as: “The person slowly turns toward the lake. A light breeze moves the hair. The camera makes a gentle forward move.” Inspect whether the person remains the same, the turn is continuous and the background perspective matches the camera.
Keep the starting image, prompt, model revision, seed, dimensions, frame count, scheduler and relevant guidance settings. A seed helps compare changes within one configuration, but a different frame count or resolution can change the sampled trajectory.
Diagnose what went wrong
| Symptom | Inspect first | A useful next test |
|---|---|---|
| Subject changes identity | Starting visual and motion extent | Reduce motion and compare a shorter shot |
| Camera and subject motion conflict | Prompt describes both ambiguously | Specify a fixed camera or one camera move |
| Hands or small details deform | Motion, occlusion and frame detail | Simplify the action and inspect original frames |
| Objects disappear | Visibility and scene complexity | Use fewer interacting objects |
| Generation exceeds memory | Dimensions, frames and runtime allocations | Reduce one workload dimension |
These tests help isolate the failure. Avoid changing prompt, seed, duration and sampler together if the goal is to learn which control matters.
Build a sequence from manageable shots
A practical production workflow is to establish a shot, generate a short clip, review it and edit accepted clips together. Image-to-video can help carry a chosen appearance into a shot. Reusing the last frame as a new starting point can improve continuity, though it can also propagate distortion.
Treat each transition as an editing decision. Check subject identity, screen direction, lighting and camera position across the cut. A polished sequence depends on selection, continuity and editing as well as generation.
For the underlying image process, read How AI Image Generation Works. The image settings guide explains seeds, sampling and guidance before those controls are extended to video.