How Does AI Image Generation Work? Diffusion Models Explained
Learn how AI image generators turn text into images, including noise, denoising, latent space, text encoders, guidance, samplers, seeds, and diffusion steps.
Approximately 4 min read
A text-to-image model uses a prompt to guide the creation of an image. In many influential systems, generation starts from noise and repeatedly updates an image representation toward a sample consistent with the conditioning.
Three pieces work together: a text representation, a learned image-generation model and a numerical sampling process. Keeping those roles separate helps explain why the same prompt can produce different pictures and why settings behave differently across model families.
Learn to remove noise
In a diffusion training setup, noise is added to training examples at different levels. The neural network learns a prediction that helps reverse that corruption, conditioned on information such as a text description.
During generation, the system starts with a noise sample and repeatedly uses the trained predictor and scheduler to update it. Details of the prediction target vary by formulation. Flow-matching systems use a related generation picture but learn a different kind of trajectory; “diffusion” should not be used to assume every generator has identical equations.
The model learns statistical structure from training data. It can generate new arrangements, but its training data and learned biases influence what it produces. It may also reproduce recognizable material, which matters when evaluating outputs and their intended use.
Text conditioning guides the result
A tokenizer and text encoder turn a prompt into numerical representations. The image model uses these representations through mechanisms such as cross-attention or joint processing to make its updates sensitive to the description.
For a prompt like “a red bicycle beside a stone wall,” the system must coordinate objects, colour, placement, texture and lighting. A prompt does not specify every pixel. Many different images satisfy the same description, so the initial random state helps determine which result is sampled.
Classifier-free guidance is one way to strengthen conditioning in compatible pipelines. Its scale balances conditional and unconditional predictions. Excessive guidance can produce harsh or distorted results, and the suitable range depends on the model.
Why latent space matters
Many generators work in a compressed latent representation rather than updating every output pixel directly. An encoder maps an image to a latent during training or image-to-image preparation; a decoder turns the generated latent back into visible pixels.
| Stage | Representation | Job |
|---|---|---|
| Prompt encoding | Text features | Describe the requested content |
| Initial state | Random latent | Provide a starting point for sampling |
| Generation updates | Evolving latent | Apply the model and conditioning |
| Image decoding | Pixels | Produce the viewable image |
Compression reduces the size of the main generation problem, but the decoder can still affect detail and appearance.
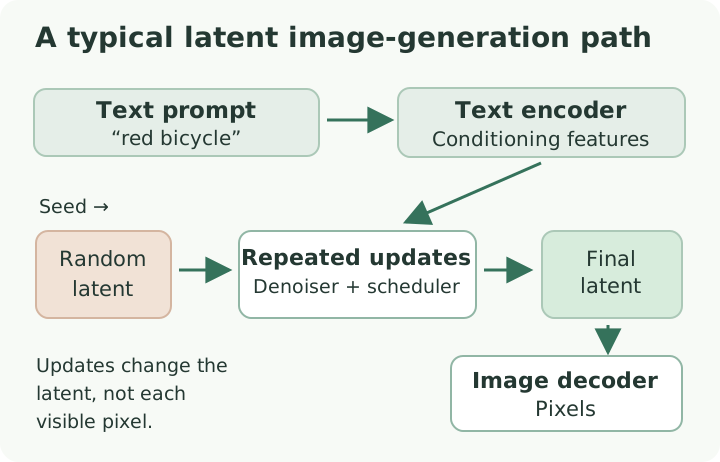
This shows a latent diffusion-style pipeline. Architectures and prediction targets differ, including flow-matching variants. Changing a VAE or decoder is therefore part of changing the generation configuration.
Follow one generation
Suppose you request a red teapot on a wooden table. The text encoder represents the description. A seeded generator supplies the initial latent. The scheduler selects noise levels, and the model repeatedly updates the latent using the prompt conditioning. The decoder finally converts it into pixels.
Changing the seed can change the composition. Changing the step count changes how many numerical updates are made. Changing the scheduler changes the update trajectory. Changing dimensions alters the latent’s geometry and computation cost.
Keep these variables fixed when trying to understand one effect. A different seed, resolution and guidance value together produce a new result without telling you which change caused it.
Image-to-image and targeted editing
Image-to-image generation starts from a supplied image representation and adds noise before regenerating it. Denoising strength controls how far that process can depart from the input. Lower strength generally preserves more structure; higher strength permits larger changes.
Inpainting adds a spatial constraint so selected regions can be regenerated. Additional conditioning can provide depth, pose or other structural information. These workflows constrain different parts of the generation problem, which is why a reference image or control signal can achieve a composition that a longer prompt cannot reliably specify.
Understand failures through the pipeline
Incorrect object counts, inconsistent geometry and unreadable text can arise because plausible image synthesis is different from enforcing a precise symbolic specification. Inspect the output against the actual requirement rather than judging only whether it looks attractive.
For practical tuning, use the image settings guide. Start with a supported model configuration, save its metadata and compare one change at a time.