Qwen3.8 MTP 'output_hc_norm.weight not found': Current llama.cpp Fix Status
If a Qwen3.8-Flash-Next MTP draft GGUF fails on output_hc_norm.weight, separate target-model loading from detached draft-head compatibility, inspect the sidecar tensor layout, and verify the exact llama.cpp MTP implementation.
Approximately 3 min read
Quick answer: if the Qwen3.8-Flash-Next target runs normally but adding an MTP draft GGUF fails on output_hc_norm.weight, the problem is in the draft-head/sidecar contract, not the target model. Confirm the target without -md, then compare the draft file layout with the exact MTP implementation your llama.cpp build contains.
As of October 17, upstream issue #29174 and MTP PR #27836 are still open. Companion PR #28097, which targeted draft-head-only GGUFs, was closed without merge.
The failure looks like:
llama_model_load: error loading model:
check_tensor_dims: tensor 'output_hc_norm.weight' not found
Remove the draft model and speculative options, then check that the target initializes and generates. Save that successful command alongside the failing MTP command. The difference identifies which additional component introduced the failure.
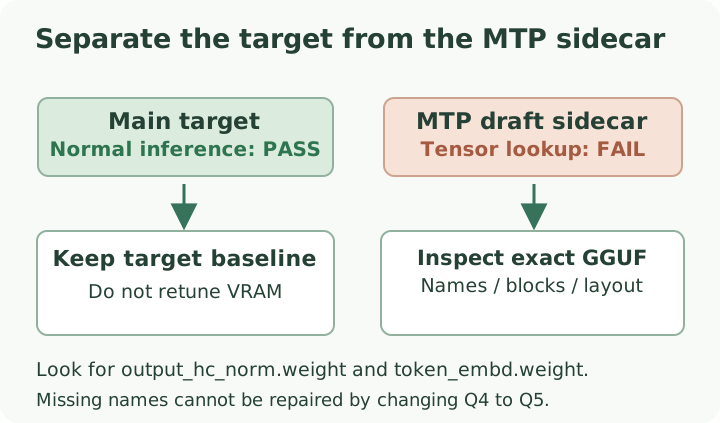
What the missing name tells you
In upstream issue #29174, draft files failed on output_hc_norm.weight or, with another layout, token_embd.weight, while the target model ran.
A detached head may omit tensors shared with the target. A loader expecting a self-contained model can request those absent tensors. Other failures arise when the exporter and loader disagree about names or block indices.
Inspect the sidecar’s tensor inventory against the loader’s expectation:
| Check | Interpretation |
|---|---|
| Requested tensor is absent | Determine whether the file is head-only and how shared tensors should be supplied |
| Related tensors exist under another block index | Check the exporter’s indexing convention |
| Target itself fails without the sidecar | Diagnose the target loader before the draft path |
| Pair works on the author’s documented runtime revision | Compare loader changes between that revision and yours |
For example, upstream MTP discussions describe hyper-connection tensors indexed at their position in the complete model, such as blk.48.hc_..., while a detached-head loader expects relative indexing such as blk.0.hc_....
Renaming a tensor without checking its role and shape can replace a clear load failure with an incorrect graph. Match the documented exporter and loader conventions instead.
Match the runtime to the exported head
The presence of draft-mtp in help establishes that the command-line parser recognizes the option. Compatibility also depends on architecture, exported head layout, and the implementation in that runtime revision.
Check the sidecar’s model card or publishing discussion for the target family, exporter revision, llama.cpp commit or PR, and required options. PR #27836 and PR #28097 provide implementation context for the upstream MTP work.
Compare the target alone, the target with the published sidecar, and—if available—the same pair on the revision documented by its author. Record the first loader error for each run.
Changing Q4 to Q5 cannot supply a tensor that the export omitted. If a conversion pipeline dropped required state, repair or replace that export.
Once the pair loads and produces valid output, measure acceptance and throughput separately. Until then, the useful evidence is the exact model pair, tensor inventory, runtime version, and the successful target-only control.