llama.cpp Max Context vs GPU Memory: Find the Real Limit
Find the largest llama.cpp context that fits your GPU by separating weights, KV cache, compute buffers, concurrency, auto-fit, and backend limits.
Approximately 3 min read
To find a usable context limit, hold the model and placement fixed, increase context, and inspect the first allocation that fails. A model card’s context window describes model support; the runtime still needs memory for weights, cache, and working buffers.
Start with one sequence and an explicit context:
llama-cli -m model.gguf -c 8192 -np 1 -n 1 -p "test"
Then try 16,384, 32,768, and 65,536 tokens without changing other settings. When a value fails, test between the last passing and first failing values.
The one-token launch checks initialization. A capacity setting also needs a realistic long prompt and the expected generation length before it becomes a useful serving limit.
Identify what ran out of memory
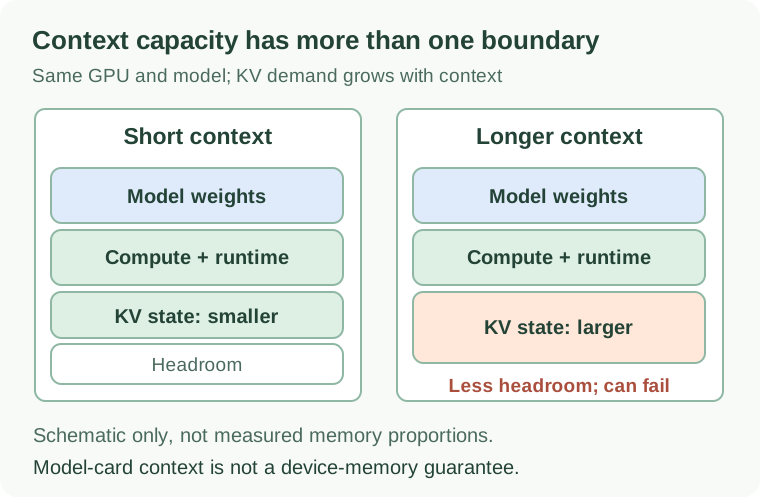
Longer context increases cache demand alongside weights and runtime allocations; the blocks illustrate the relationship rather than measured proportions.
| First failure | What to investigate |
|---|---|
| KV-cache buffer allocation | Context, cache precision, parallel sequences, cache placement |
| Compute prompt-processing buffer allocation | Batch, physical micro-batch, attention path, context |
| Model-weight allocation | Weight size and GPU layer placement |
| Allocation on one device only | Per-device placement and free memory |
The KV-cache allocation guide and compute-buffer guide follow those two failure paths in more detail.
KV requirements depend on attention structure, cached layers, head dimensions, and precision. Two models with similar parameter counts can therefore have very different context-memory costs.
Check resolved settings
In the cited llama.cpp documentation, -c 0 loads the context value from the model. Use a deliberate value during capacity testing so initialization does not request a larger cache than intended.
Auto-fit controls such as --fit, --fit-target, and --fit-ctx adjust unset arguments to fit available device memory. Inspect the resulting context and placement in the log. A launch that succeeds at 8K has not demonstrated that a required 64K workload fits.
For a server, also inspect total and per-slot context. Parallel sequences and unified-KV settings affect how available cache capacity is shared. Establish a single-sequence baseline before adding the intended concurrency.
Move the boundary one variable at a time
Lower-precision keys and values can reduce cache memory on supported paths. The -ctk and -ctv controls are separate from GGUF weight quantization. Compare memory, speed, and output behavior after a cache-format change.
Reducing GPU-resident layers frees device memory by moving model work to CPU and host RAM, usually at a speed cost. If that trade-off is needed, the broader VRAM reduction guide covers the available controls.
With multiple GPUs, inspect allocations per device:
llama-cli --list-devices
nvidia-smi
The cards do not form a flat memory pool. A buffer can exhaust one device while another retains free space.
Experimental tensor split needs particular care: the cited multi-GPU documentation does not support auto-fit for that mode. Check architecture and KV-format compatibility before treating every failed tensor-split run as a capacity problem.
Save the passing workload
Keep the exact GGUF, runtime commit, backend, GPU placement, KV types, parallel count, batch settings, longest tested prompt, and peak memory per device with the result.
Finally, repeat the workload under realistic conditions: concurrent requests, other GPU processes, or multimodal inputs where applicable. A startup that consumes almost all available VRAM leaves little room for those demands. The useful limit is the largest setting that completes the intended workload reliably.